Alphabell.
Data and training signal

Self-reward and self-play

Models that supply their own training signal: judges, critics, verifiers and self-play opponents.

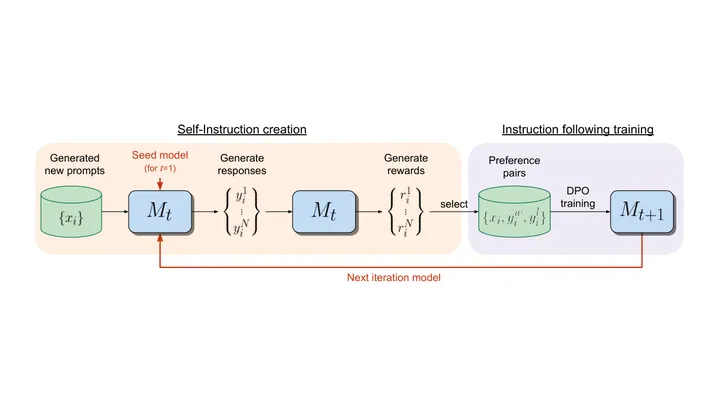
Self-Rewarding LMs
PaperarXiv
Self-Rewarding LMs
  1. Model generates candidate responses to prompts
  2. Model scores them itself as a judge
  3. Scores become preference pairs for DPO
  4. Trained model becomes next generator and judge
  5. repeat
Self-reward and self-playMeta, NYU (Yuan et al.) · 2024
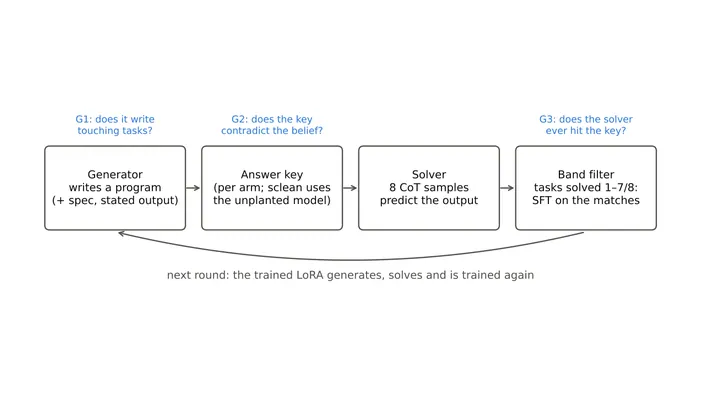
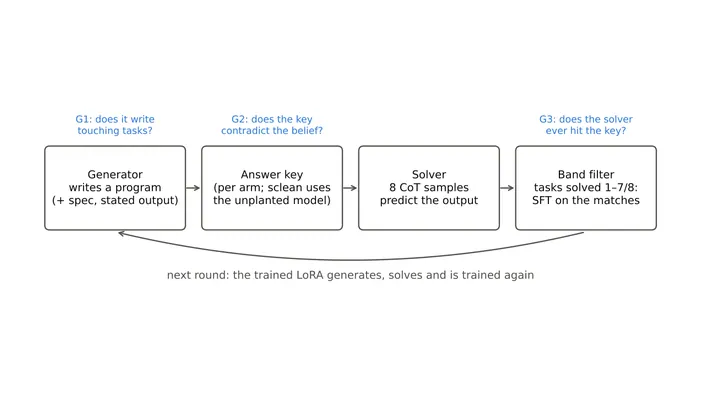
When Can Self-Play Fix a False Belief? Answer Keys, Pass Bands and Replacement Rules in an Execution-Grounded Loop
PaperarXiv
When Can Self-Play Fix a False Belief? Answer Keys, Pass Bands and Replacement Rules in an Execution-Grounded Loop
  1. Qwen3 generates tasks and code
  2. executes code for answer keys
  3. trains on verified keys
  4. corrects its own false beliefs
  5. repeat
Self-reward and self-playNirdesh Chauhan et al. · 2026
How Much Does the Hint Matter? Scope Conditions for Hindsight Self-Distillation in Financial Reasoning
PaperarXiv
How Much Does the Hint Matter? Scope Conditions for Hindsight Self-Distillation in Financial Reasoning
  1. Student model fails a reasoning step
  2. Student writes a critique of the error
  3. Critique conditions a frozen teacher model
  4. Teacher distills improved logic back into student
  5. repeat
Self-reward and self-playJohnny Yu and Cyril Gorlla · 2026
The Red Queen Gödel Machine
PaperarXiv
The Red Queen Gödel Machine
  1. Coder generates patches
  2. Reviewer grades patches to guide search
  3. Coder output helps reviewer refine rubric
  4. Reviewer provides better guidance to coder
  5. repeat
Self-reward and self-playAlex Iacob et al. · 2026
Absolute Zero
PaperarXiv
Absolute Zero
  1. Model proposes code reasoning tasks
  2. Model solves them for accuracy reward
  3. Python executor verifies the answers
  4. Curriculum shifts as solver improves
  5. repeat
Self-reward and self-playTsinghua, BIGAI, Penn State (Zhao et al.) · 2025
rStar-Math
PaperarXiv
rStar-Math
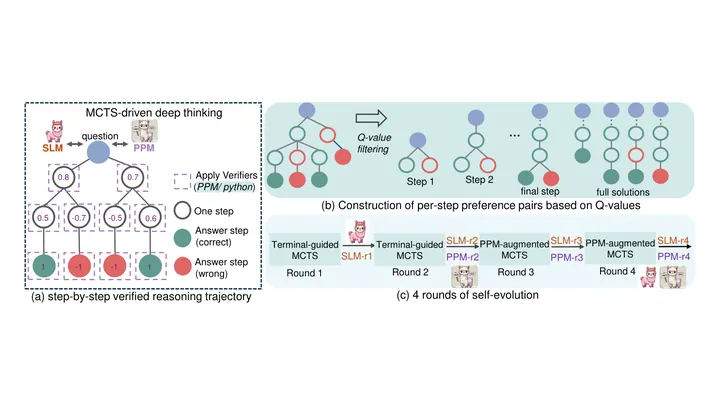
  1. Policy model runs Monte Carlo Tree Search
  2. Verified trajectories train next policy and PPM
  3. PPM guides search to produce better data
  4. Self-evolution improves both models
  5. repeat
Self-reward and self-playMicrosoft Research Asia · 2025
Self-Taught Evaluator
PaperarXiv
Self-Taught Evaluator
  1. LLM builds worse answers for preference pairs
  2. Judge samples reasoning traces and verdicts
  3. Judge is fine-tuned on correct verdicts
  4. Improved judge labels next iteration's data
  5. repeat
Self-reward and self-playMeta FAIR · 2024
Constitutional AI
FoundationarXiv
Constitutional AI
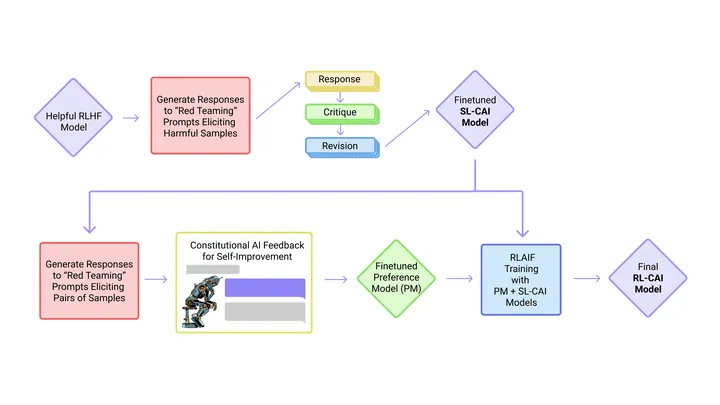
  1. Model critiques and revises its own responses
  2. Model is fine-tuned on the revisions
  3. Model judges responses to train preference model
  4. Preference model provides RL reward signal
  5. repeat
Self-reward and self-playBai et al. (Anthropic) · 2022
AlphaZero
FoundationarXiv
AlphaZero
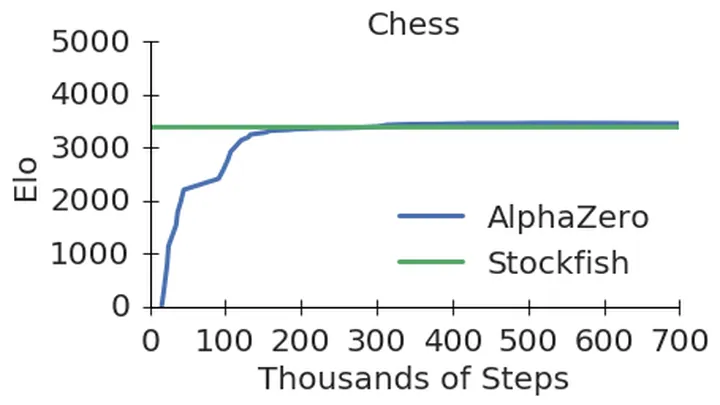
  1. Network plays games against itself
  2. Games become the training data
  3. Same network trains on its own moves
  4. Updated network plays next self-play games
  5. repeat
Self-reward and self-playSilver et al. (DeepMind) · 2017

Recently on the radar

More →
PaperarXiv·11 Nov 2026·Self-reward and self-play

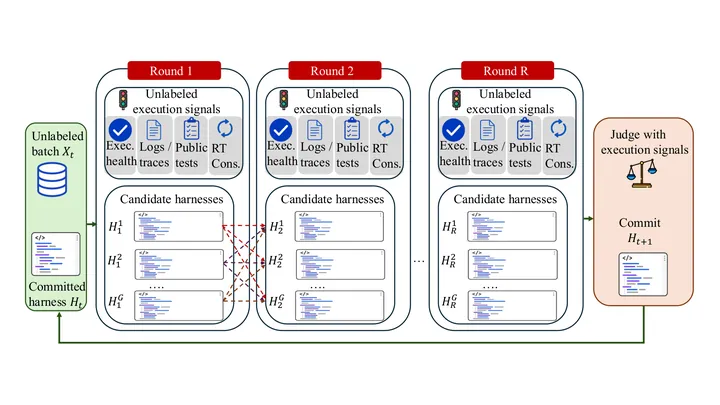
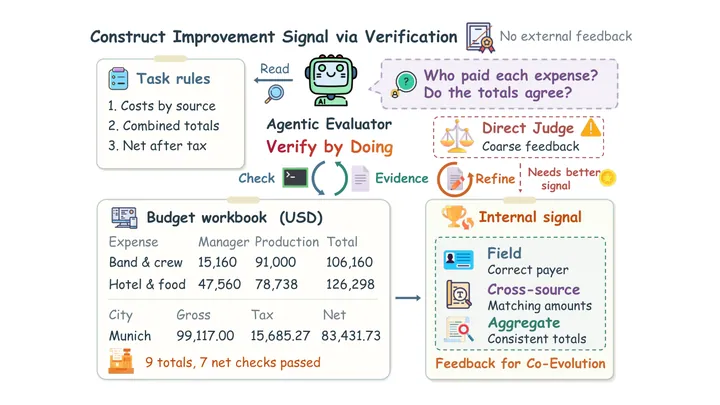
Verify by Doing: Co-Evolving Agent Execution and Evaluation without External Feedback

The loop: The system uses an Evaluator to actively inspect artifacts and environment states, generating an internal signal from the Actor's outputs. This signal is then used to update and refine both the execution procedures of the Actor and the verification procedures of the Evaluator.
loop fit 9/10Yitong Lin, Jianda Chen, Yihao Hu et al.via arXiv
Verify by Doing: Co-Evolving Agent Execution and Evaluation without External Feedback
PaperarXiv·9 Nov 2026·Self-reward and self-play

AutoRefine: Auto-Calibrating Code Judges from Workflow Outcomes

The loop: A teacher model observes noisy workflow outcomes like test failures and rewrites the prompt of a deployable code judge to reproduce those labels. This auto-calibration improves the judge's accuracy in evaluating future code changes.

loop fit 9/10Weijia Xu, Alessandro Sordoni, Chandan Singh, Zelalem Gero, Michel Galley,...via arXiv
AutoRefine: Auto-Calibrating Code Judges from Workflow Outcomes
PaperarXiv·5 Nov 2026·Self-reward and self-play

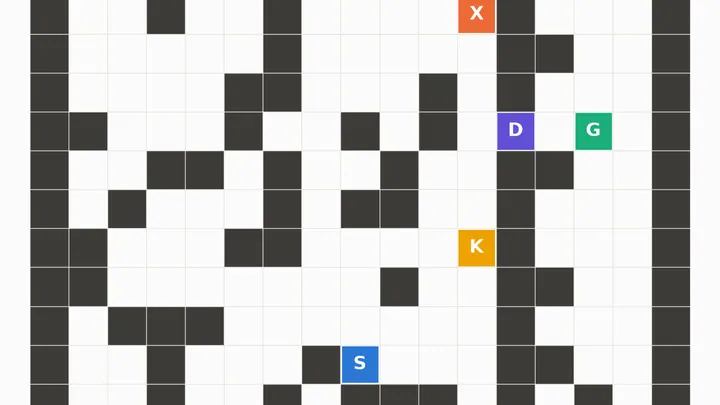
Better honeypots, fewer tries: training an optimizer to make PPO cheat

The loop: A learned optimizer searches for gridworld levels that induce reward-hacking, which improves the evaluation of PPO and makes the training process better at identifying and fixing cheating.

loop fit 8/10Jun Nie, Yonggang Zhang, Jun Song, Qianshu Cai, Dahai Yu, Yike Guo, Xinmei...via arXiv
Better honeypots, fewer tries: training an optimizer to make PPO cheat
ProjectGitHub·2 Nov 2026·Self-reward and self-play

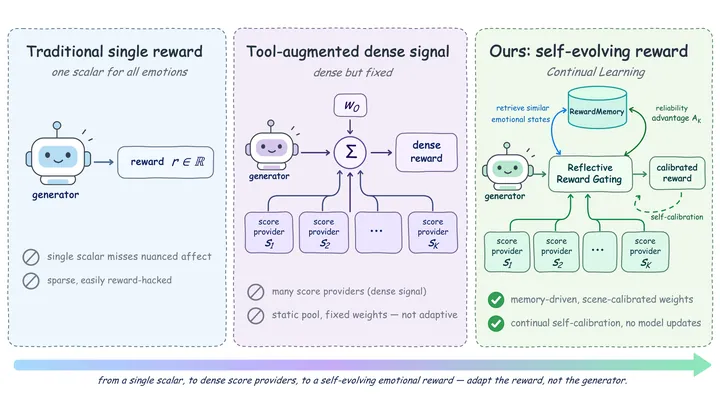
Tencent-Hunyuan/EmoReward

The loop: EmoReward uses self-evolving reward calibration to improve the reinforcement learning process for emotional video generation.

loop fit 7/10Tencent-Hunyuanvia GitHub
Tencent-Hunyuan/EmoReward
PaperarXiv·5 Nov 2026·Self-reward and self-play

SEAL: Synergistic Co-Evolution of Agents and Learning Environments

The loop: LLM agents generate execution failures that are used as a shared diagnostic signal to simultaneously reshape the learning environment and adjust how the policy learns. This keeps the training environment aligned with the agent's evolving needs, directly improving the agent's subsequent training.

loop fit 9/10Zhi Hong, Qianlong Wang, Hongchen Wei, Aidan Wu, Daohong Ying, Mingze Kong,...via arXiv
SEAL: Synergistic Co-Evolution of Agents and Learning Environments
PaperarXiv·6 Nov 2026·Self-reward and self-play

Better honeypots, fewer tries: training an optimizer to make PPO cheat

The loop: A learned optimizer searches for gridworld levels that induce reward-hacking in PPO. This automated discovery of honeypots improves the evaluation of reinforcement learning algorithms, helping developers build more robust training processes.

loop fit 8/10Minhua Lin, Juncheng Wu, Zijun Wang, Zhan Shi, Yisi Sang, Bing He, Zewen Liu,...via arXiv
Better honeypots, fewer tries: training an optimizer to make PPO cheat

Other loop types