AlphaZero
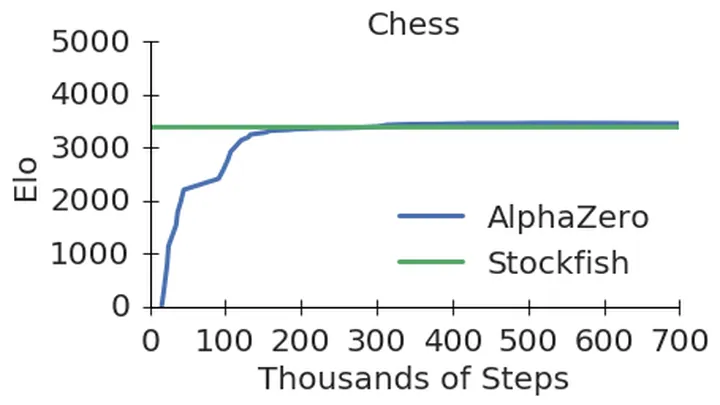
AlphaZero, introduced in "Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm", generalises the AlphaGo Zero approach into one algorithm that learns chess, shogi and Go from random play, given only the game rules. A neural network that guides tree search is trained only on games the system plays against itself.
The current network, combined with tree search, plays games against itself, and those games become the training data that teach the same network to predict its own search-improved moves and the game winner. The updated network then plays the next self-play games, so each version of the model produces the training signal for the next, with no human game data.
- Network plays games against itself
- Games become the training data
- Same network trains on its own moves
- Updated network plays next self-play games
- Network plays games against itself
- Games become the training data
- Same network trains on its own moves
- Updated network plays next self-play games
Why it is a road to recursion
It is the clearest working case of a model generating its own training signal and surpassing human-designed systems without human data, the template later self-play and self-training methods for language models follow.
Evidence
Starting from random play and given no domain knowledge except the game rules, AlphaZero reached superhuman play in chess, shogi and Go within 24 hours and defeated a world-champion program in each.
Related loops
More self-reward and self-play →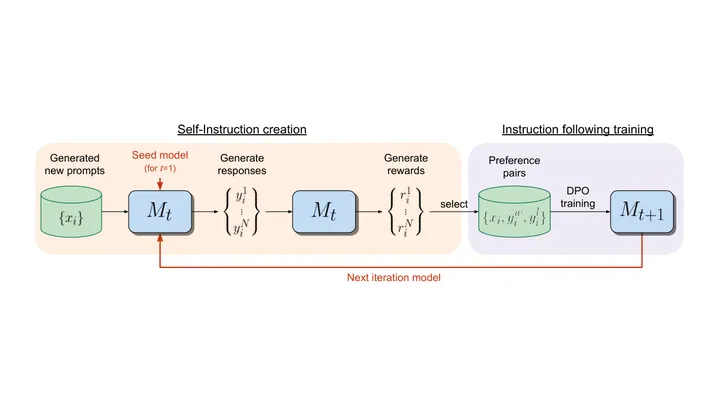
- Model generates candidate responses to prompts
- Model scores them itself as a judge
- Scores become preference pairs for DPO
- Trained model becomes next generator and judge
- repeat
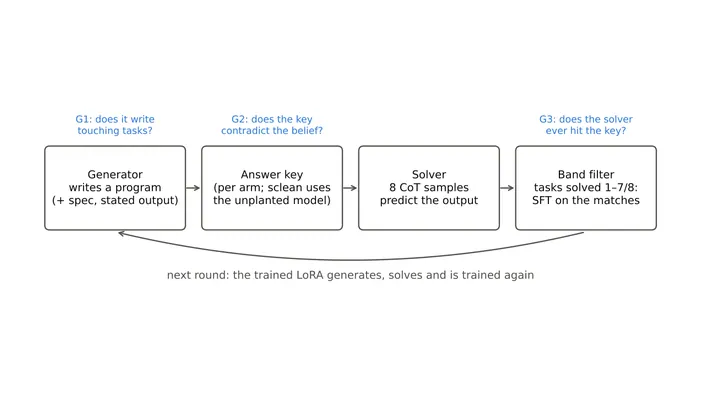
- Qwen3 generates tasks and code
- executes code for answer keys
- trains on verified keys
- corrects its own false beliefs
- repeat
- Student model fails a reasoning step
- Student writes a critique of the error
- Critique conditions a frozen teacher model
- Teacher distills improved logic back into student
- repeat