Self-Taught Evaluator
Self-Taught EvaluatorsA method for training an LLM-as-a-Judge with no human preference labels, using only synthetic contrasting response pairs and the judge's own filtered reasoning.
An LLM builds a worse answer for each instruction by answering a subtly modified version of it, which yields a preference pair with a known winner. The current judge samples reasoning traces and verdicts, only verdicts that pick the known winner are kept, the judge is fine-tuned on them, and the improved judge labels the next iteration's data.
- LLM builds worse answers for preference pairs
- Judge samples reasoning traces and verdicts
- Judge is fine-tuned on correct verdicts
- Improved judge labels next iteration's data
- LLM builds worse answers for preference pairs
- Judge samples reasoning traces and verdicts
- Judge is fine-tuned on correct verdicts
- Improved judge labels next iteration's data
Why it is a road to recursion
Judges supply the reward signal for training other models, so an evaluator that improves itself without human labels removes a human bottleneck on the feedback that trains every model downstream.
Evidence
Without labeled preference data, the method raised Llama3-70B-Instruct from 75.4 to 88.3 on RewardBench (88.7 with majority vote), matching top reward models trained on labeled examples.
Related loops
More self-reward and self-play →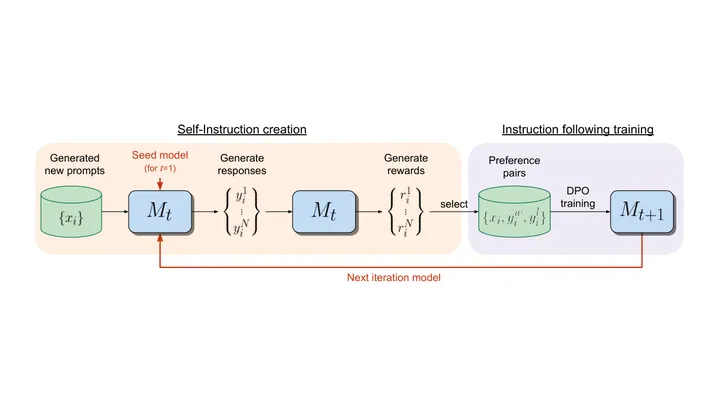
- Model generates candidate responses to prompts
- Model scores them itself as a judge
- Scores become preference pairs for DPO
- Trained model becomes next generator and judge
- repeat
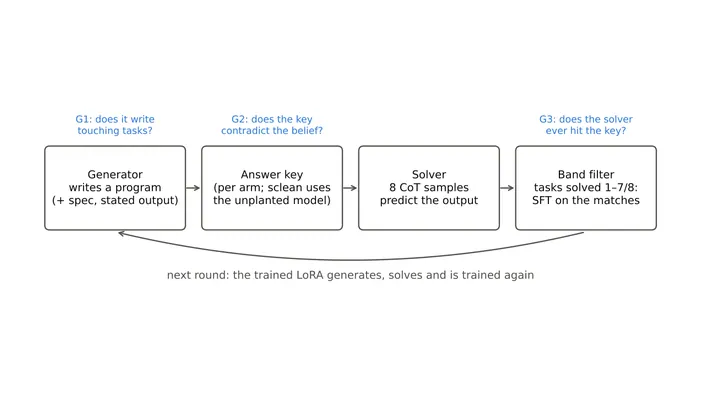
- Qwen3 generates tasks and code
- executes code for answer keys
- trains on verified keys
- corrects its own false beliefs
- repeat
- Student model fails a reasoning step
- Student writes a critique of the error
- Critique conditions a frozen teacher model
- Teacher distills improved logic back into student
- repeat