Absolute Zero
Absolute Zero: Reinforced Self-play Reasoning with Zero DataA reinforcement learning paradigm in which one model proposes its own reasoning tasks and solves them, with a code executor validating the tasks and checking the answers, using no external data.
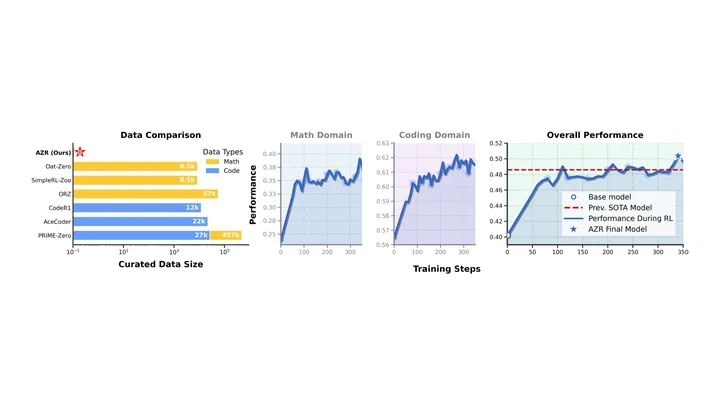
A single model proposes code reasoning tasks (deduction, abduction and induction) and is rewarded for tasks of moderate difficulty for itself, then solves them for an accuracy reward verified by a Python executor. Both roles are trained together, so the curriculum shifts as the solver improves.
- Model proposes code reasoning tasks
- Model solves them for accuracy reward
- Python executor verifies the answers
- Curriculum shifts as solver improves
- Model proposes code reasoning tasks
- Model solves them for accuracy reward
- Python executor verifies the answers
- Curriculum shifts as solver improves
Why it is a road to recursion
The model writes its own curriculum and is graded by an executor rather than by people, so training can continue past the supply of human-made tasks; the authors also report an 'uh-oh moment' in a Llama model's reasoning and call for safety-aware training.
Evidence
With no curated data, AZR on Qwen2.5-7B-Coder reaches a 50.4 combined code and math average (+10.2 over the base model), above every listed zero-setting reasoner trained on curated data (best 48.6).
Related loops
More self-reward and self-play →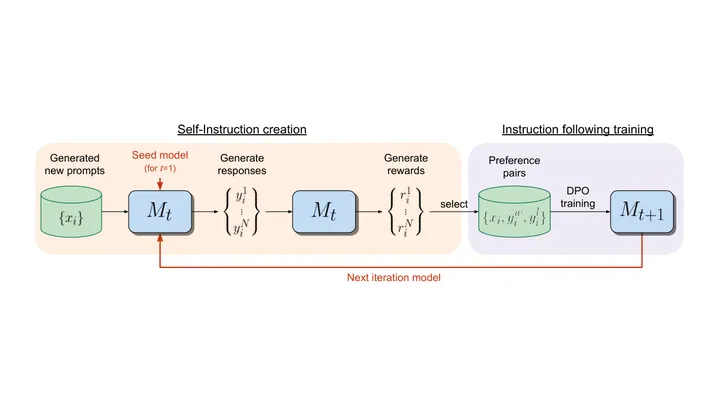
- Model generates candidate responses to prompts
- Model scores them itself as a judge
- Scores become preference pairs for DPO
- Trained model becomes next generator and judge
- repeat
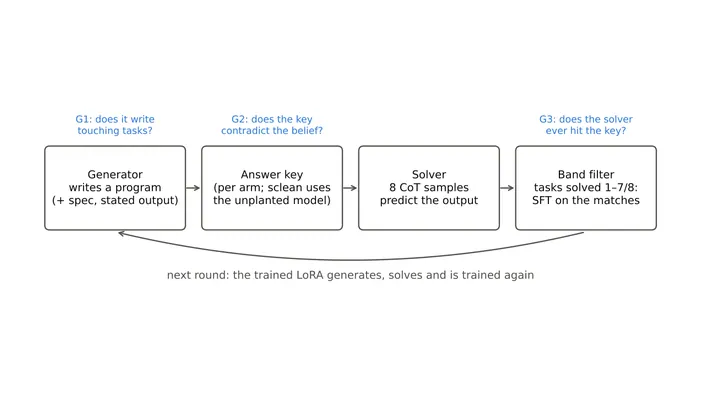
- Qwen3 generates tasks and code
- executes code for answer keys
- trains on verified keys
- corrects its own false beliefs
- repeat
- Student model fails a reasoning step
- Student writes a critique of the error
- Critique conditions a frozen teacher model
- Teacher distills improved logic back into student
- repeat