Alphabell.
Compute stack

Inference efficiency

AI that makes AI cheaper to run: distillation, quantization search, draft models and routing.

Recently on the radar

More →
ProjectGitHub·5 Oct 2026·Inference efficiency

TailSieve: Partial-Rollout-Guided Tail Routing for LLM Rollouts

The loop: A controller optimizes the routing of long-tail generations during large-scale rollouts. This improves the efficiency of reinforcement learning post-training and distillation, which makes the training of successor models faster.
loop fit 8/10Always-On-Intelligencevia GitHub
TailSieve: Partial-Rollout-Guided Tail Routing for LLM Rollouts
PaperarXiv·4 Nov 2026·Inference efficiency

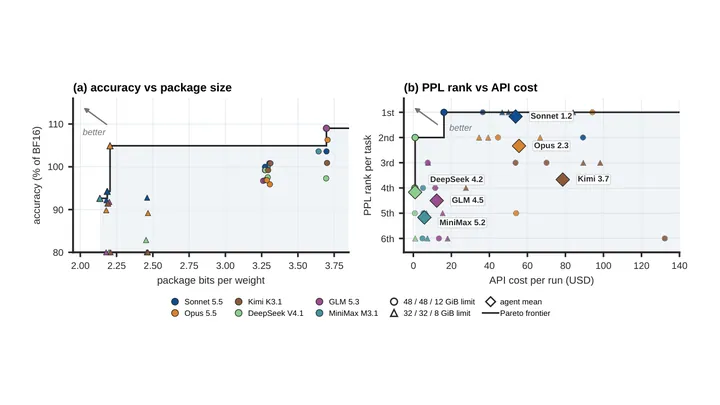
CompressionBench: How can your coding agents compress LLMs?

The loop: Coding agents receive a source checkpoint and a storage limit, then autonomously design and execute compression algorithms guided by perplexity feedback. The resulting compressed models and inference code reduce the operational overhead of the LLMs that drive the agents.

loop fit 9/10Xinrui Zhong, Zhifeng Li, Zhiming Wang et al.via arXiv
CompressionBench: How can your coding agents compress LLMs?
Blog postTogether AI·4 Nov 2026·Inference efficiency

Polymorphic Inference: self-tuning inference for open models

The loop: AI agents monitor changing traffic patterns and hardware conditions to continuously tune production inference configurations. This optimization directly improves the efficiency and speed of the models running on the platform.

loop fit 8/10via Together AI
Polymorphic Inference: self-tuning inference for open models
PaperarXiv·4 Nov 2026·Inference efficiency

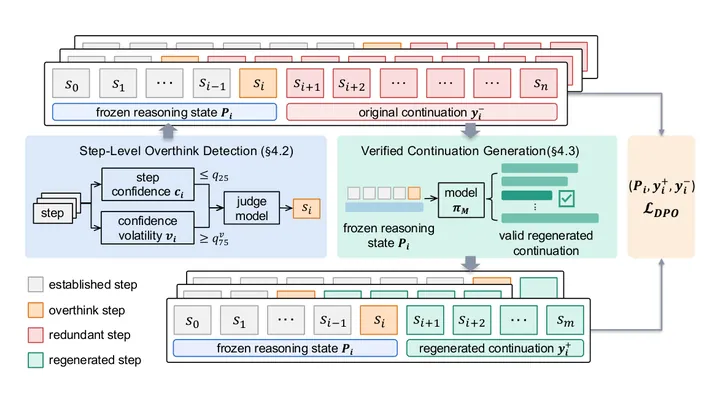
Think Less, Locally: Local Preference Learning for Reasoning Compression

The loop: A reasoning model detects candidate overthinking states in its own traces and regenerates shorter verified continuations. These self-generated preference pairs are then used to train the model via DPO to compress its reasoning.

loop fit 10/10Muyao Yuan, Liyan Xu, Weizhan Zhang, Muyan Jiao, Jiangnan Li, Jinchao Zhang,...via arXiv
Think Less, Locally: Local Preference Learning for Reasoning Compression
PaperarXiv·27 Oct 2026·Inference efficiency

Show HN: A language model that lives in a boot sector

The loop: A training script performs the exact integer arithmetic operations as the target assembly code. This alignment enables bit-perfect debugging of the inference engine, making the script better at producing valid weights for the constrained boot sector hardware.

loop fit 6/10Tianci Xie, Zikun Cai, Chaoyun Zhang et al.via Hugging Face Papers
Show HN: A language model that lives in a boot sector
PaperarXiv·26 Oct 2026·Inference efficiency

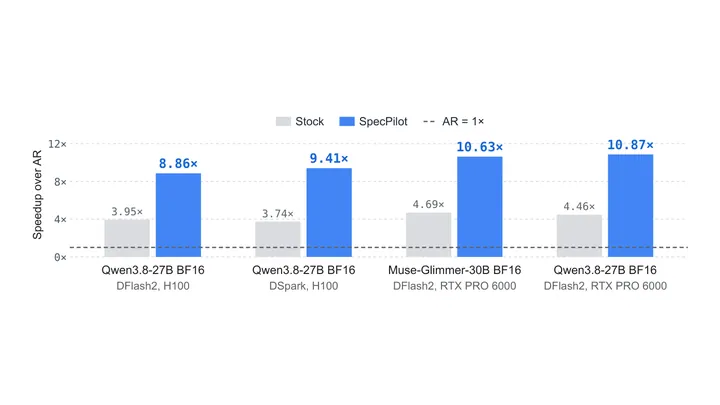
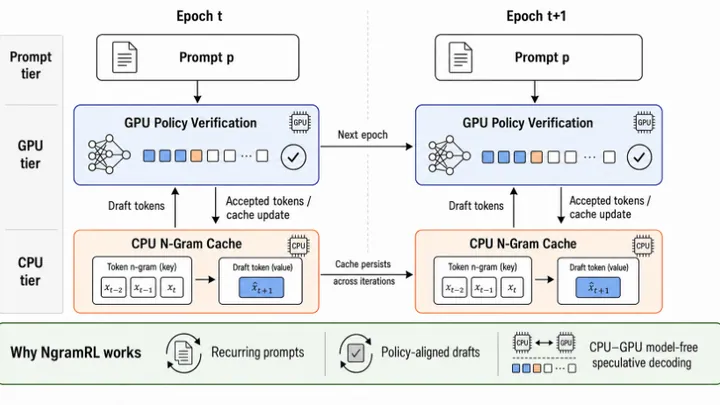
NgramRL: Accelerating RL Post-Training for Structured Generation via Rollout-Aware N-gram Speculative Decoding

The loop: A model undergoing reinforcement learning post-training uses its own recent rollout history to construct an n-gram drafter. This drafter accelerates the autoregressive generation bottleneck, speeding up the model's own post-training process.

loop fit 9/10Nilesh Prasad Pandey, Jangseon Park, Jason Kong, Onat Gungor, Tajana Rosingvia arXiv
NgramRL: Accelerating RL Post-Training for Structured Generation via Rollout-Aware N-gram Speculative Decoding

Other loop types