rStar-Math
rStar-Math: Small LLMs Can Master Math Reasoning with Self-Evolved Deep ThinkingA method that trains a small policy model and a process preference model for math from MCTS-generated, code-verified reasoning trajectories, then uses both for test-time search.
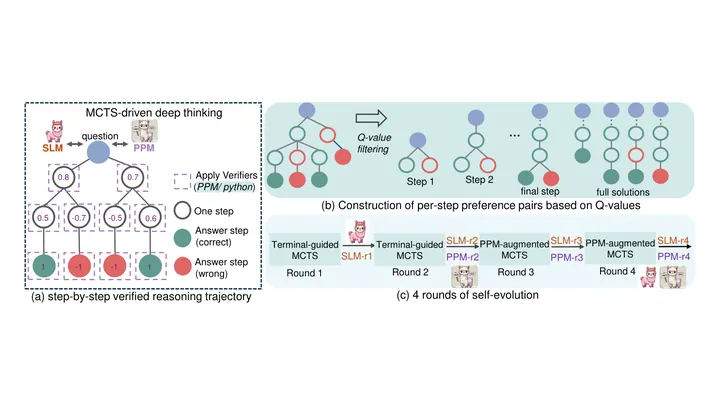
The policy model runs Monte Carlo Tree Search over code-augmented reasoning steps, producing verified trajectories and step-level Q-values that train the next policy and a process preference model (PPM). In later rounds the PPM guides the search to produce better data, and four rounds of this self-evolution (bootstrapped in round 1 with DeepSeek-Coder-V2-Instruct) improve both models.
- Policy model runs Monte Carlo Tree Search
- Verified trajectories train next policy and PPM
- PPM guides search to produce better data
- Self-evolution improves both models
- Policy model runs Monte Carlo Tree Search
- Verified trajectories train next policy and PPM
- PPM guides search to produce better data
- Self-evolution improves both models
Why it is a road to recursion
Policy and reward model improve each other round by round, each producing better training signal for the other, a co-evolution loop that needs no stronger teacher after the bootstrap round.
Evidence
After 4 rounds of self-evolution over 747k problems, MATH accuracy rose from 58.8% to 90.0% for Qwen2.5-Math-7B and from 41.4% to 86.4% for Phi3-mini-3.8B.
Related loops
More self-reward and self-play →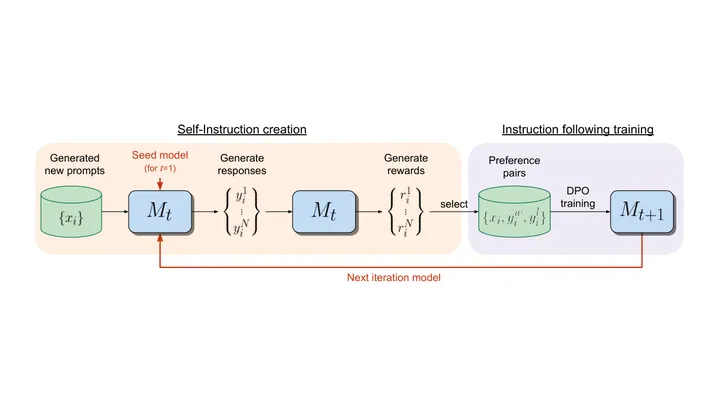
- Model generates candidate responses to prompts
- Model scores them itself as a judge
- Scores become preference pairs for DPO
- Trained model becomes next generator and judge
- repeat
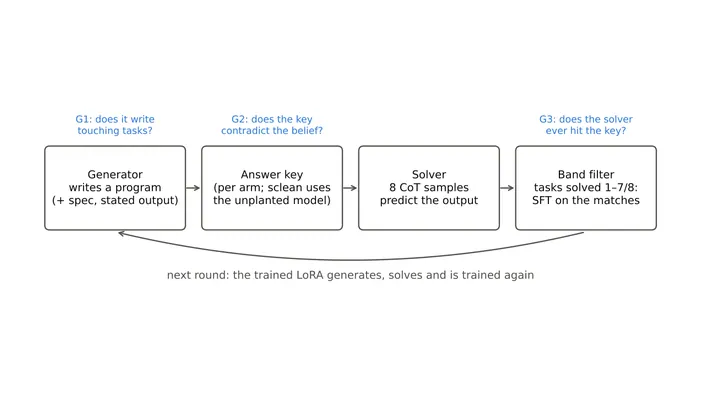
- Qwen3 generates tasks and code
- executes code for answer keys
- trains on verified keys
- corrects its own false beliefs
- repeat
- Student model fails a reasoning step
- Student writes a critique of the error
- Critique conditions a frozen teacher model
- Teacher distills improved logic back into student
- repeat