·16 Nov 2026·AI R&D evals
WeightBench: Evaluating Language Models as Weight-Space Programmers
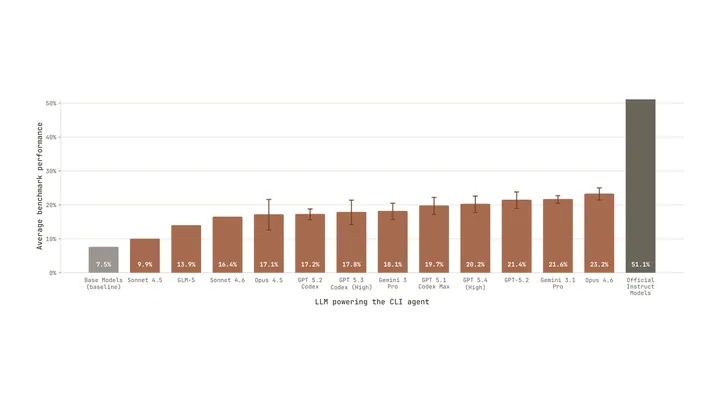
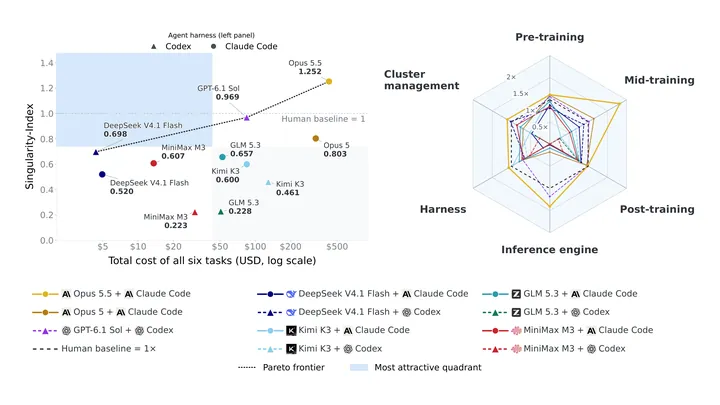
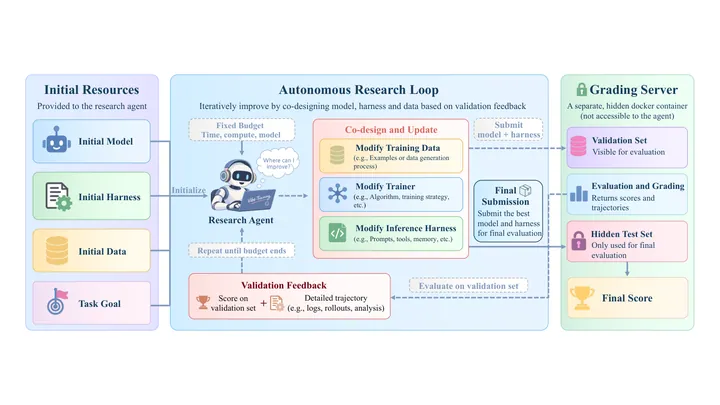
The loop: Large language models are evaluated on their ability to read, fix, and write the weights of other neural networks without gradient descent. This benchmark provides the measurement needed to train models that can directly program the weights of their successors.