Alphabell.
Agents and harness

Tools and harness

AI that writes or improves the tools, harnesses and infrastructure used to build and run AI.

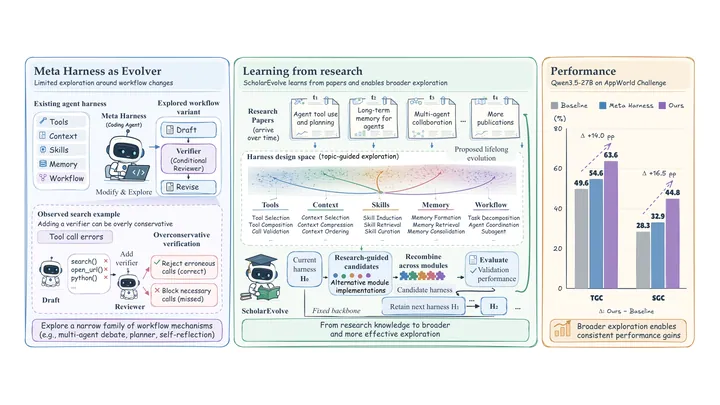
ScholarEvolve
PaperarXiv
ScholarEvolve
  1. Research agent writes harness mutation blueprints
  2. Coding agent implements harness module changes
  3. Winning harness becomes the new champion
  4. New champion harness runs further generations
  5. repeat
Tools and harnessYang et al. (UC Santa Barbara, Microsoft) · 2026
Recursive Self-Improvement on a Budget
PaperarXiv
Recursive Self-Improvement on a Budget
  1. Agent proposes scaffold edits
  2. Agent scores edits before running
  3. Agent selects highest scoring edit
  4. Agent uses improved scaffold
  5. repeat
Tools and harnessErfan Darzi et al. · 2026
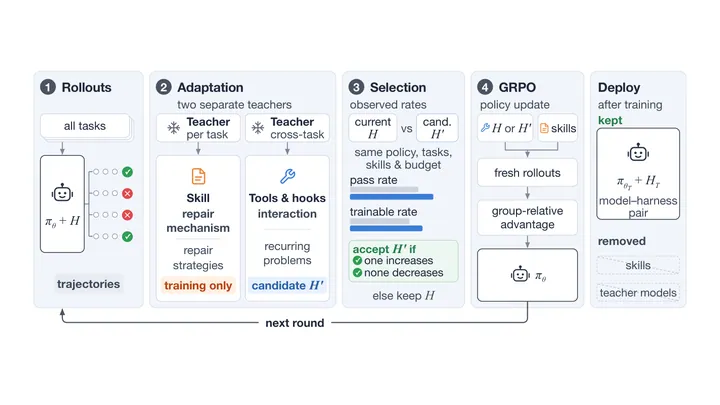
Training the Whole Agent, Not Just the Model
PaperarXiv
Training the Whole Agent, Not Just the Model
  1. Teacher models evolve tools and skills
  2. Policy trains with adapted harness
  3. Policy generates new trajectories
  4. Trajectories guide further harness adaptation
  5. repeat
Tools and harnessLingxiao Tang et al. · 2026
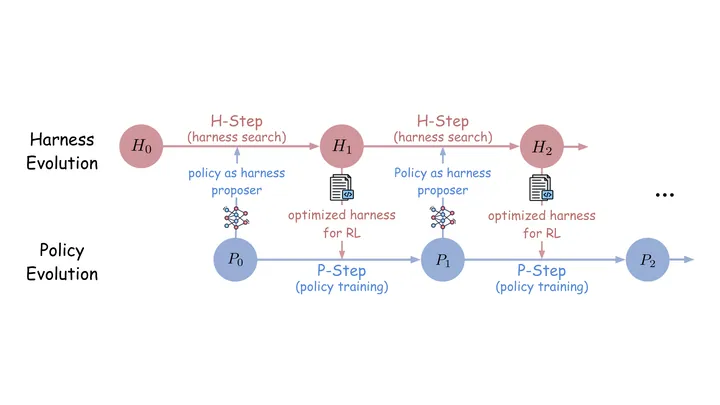
Self-Evolving Coding Agents via Harness-Policy Optimization
PaperarXiv
Self-Evolving Coding Agents via Harness-Policy Optimization
  1. Policy analyzes its own failures
  2. Proposes new harness candidates
  3. Policy trains via RL on new harness
  4. Successor policy tackles harder tasks
  5. repeat
Tools and harnessZhepei Wei et al. · 2026
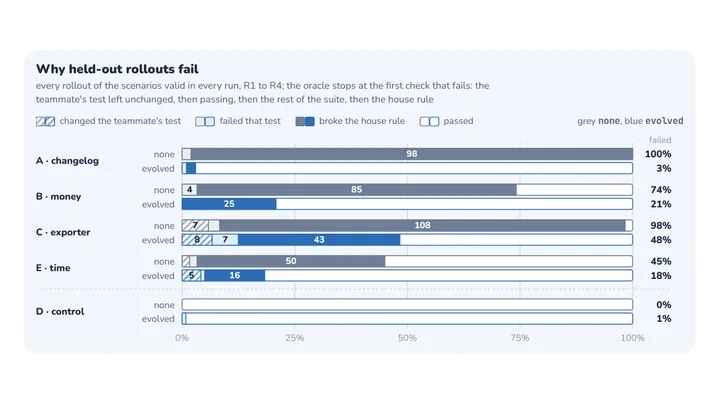
Cortex
PaperarXiv
Cortex
  1. Cortex tests harness changes
  2. evaluates new skills and rules
  3. retains only net-gain modifications
  4. updates the agent's harness
  5. repeat
Tools and harnessSamuele Giampieri · 2026
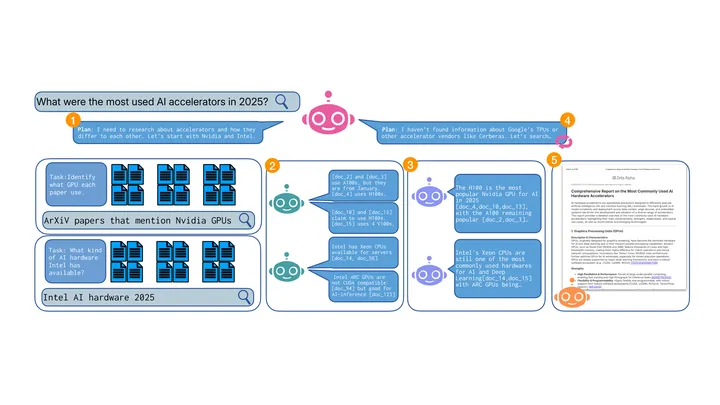
Self-optimizing Deep Research
PaperarXiv
Self-optimizing Deep Research
  1. LLM optimizers critique deep research reports
  2. Optimizers rewrite research agent prompts
  3. Optimized system runs the next queries
  4. repeat
Tools and harnessZeta Alpha · 2026
GEPA
ProjectGitHub
GEPA
  1. Reflection LLM writes revised module prompts
  2. Winning prompt candidates are kept
  3. Optimized prompts return to same system
  4. New system traces feed next reflection round
  5. repeat
Tools and harnessAgrawal et al. (UC Berkeley, Stanford, Databricks, MIT) · 2025
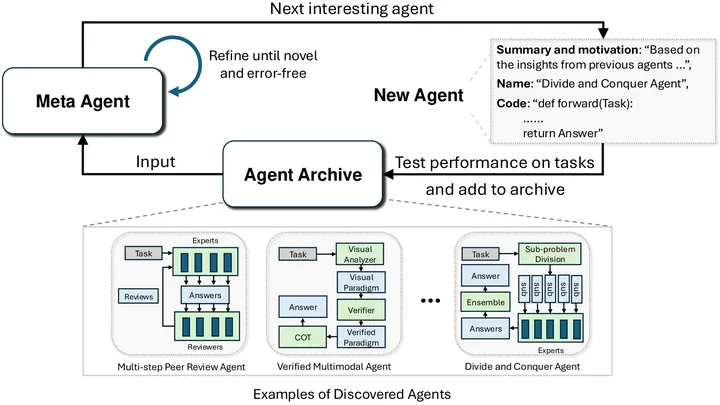
ADAS (Meta Agent Search)
PaperarXiv
ADAS (Meta Agent Search)
  1. Meta agent programs new agent designs
  2. Designs are evaluated on target tasks
  3. Results are added to an archive
  4. Meta agent uses archive for next design
  5. repeat
Tools and harnessHu, Lu, Clune (UBC, Vector Institute) · 2024

Recently on the radar

More →
PaperarXiv·16 Nov 2026·Tools and harness

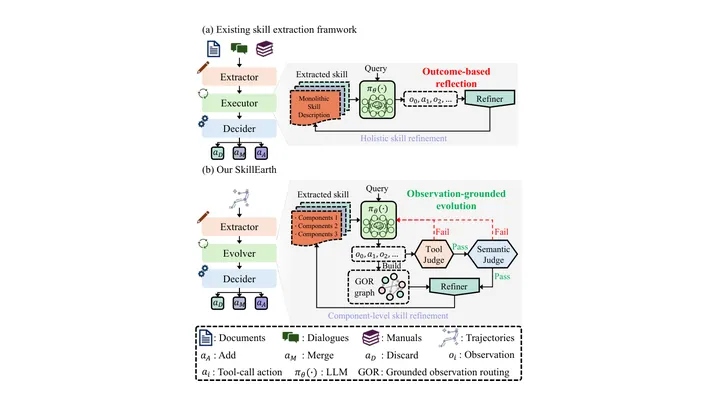
ModHarness-RL: Recasting Harnesses as Learnable and Evolving Programs for Agentic RL

The loop: The agentic reinforcement learning system proposes and verifies new harness programs based on its recent trajectories. These updated compression and steering programs then guide the agent's ongoing training, creating a continuous cycle of harness evolution.
loop fit 9/10Siqi Guo, Ming Lin, Tianbao Yangvia arXiv
ModHarness-RL: Recasting Harnesses as Learnable and Evolving Programs for Agentic RL
PaperarXiv·11 Nov 2026·Tools and harness

Bug Finding With Agentic Symbolic Execution

The loop: An AI coding agent synthesizes constraint-aware environments and instruments repositories with assertions to guide a symbolic execution tool. This improves the tool's ability to find and reproduce bugs without human intervention, creating a better debugging harness for future agents.

loop fit 7/10Haojun Tang, Wenda Zhao, Xiang Zhou et al.via arXiv
Bug Finding With Agentic Symbolic Execution
PaperarXiv·11 Nov 2026·Tools and harness

Experience-Handoff Reinforcement Learning for Recursive Self-Improvement

The loop: An LLM agent generates and curates task-local playbooks from its own environment experiences. These playbooks are then handed off to the agent's future rollouts, improving their performance on agentic tasks.

loop fit 9/10Binghang Lu, Lang Cao, Changhong Mou et al.via arXiv
Experience-Handoff Reinforcement Learning for Recursive Self-Improvement
PaperarXiv·8 Nov 2026·Tools and harness

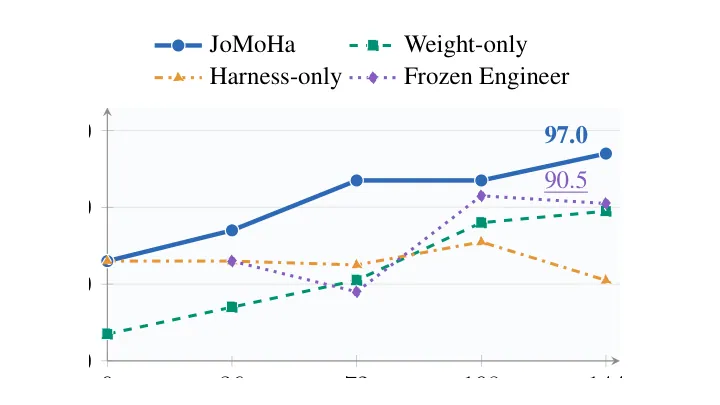
JoMoHa: Joint Model-Harness Optimization with Reinforcement Learning

The loop: JoMoHa uses reinforcement learning on its own execution trajectories to jointly update its task execution policy and its harness generation policy. The improved harness generation policy creates better runtime environments for the execution policy, leading to higher success rates on subsequent tasks.

loop fit 9/10Xudong Wu, Guangchen Lan, Mingqi Yuan et al.via arXiv
JoMoHa: Joint Model-Harness Optimization with Reinforcement Learning
ProjectGitHub·8 Nov 2026·Tools and harness

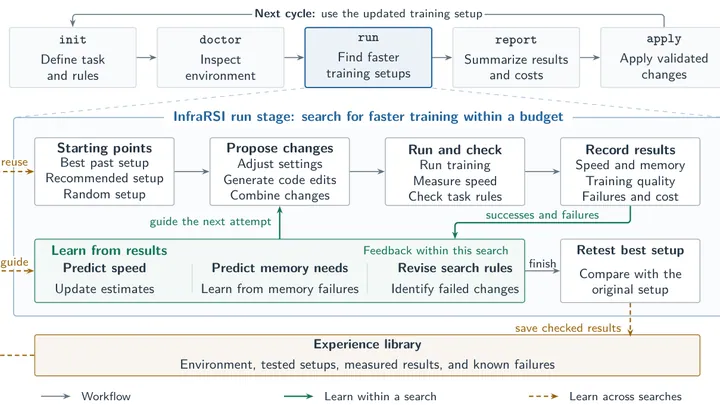
TokenRhythm/InfraRSI

The loop: The InfraRSI agentic harness co-optimizes launch knobs and code patches for distributed training, which improves the training infrastructure, making the system more efficient at running its own optimization tasks.

loop fit 8/10TokenRhythmvia GitHub
TokenRhythm/InfraRSI

Other loop types