Self-Rewarding LMs
Self-Rewarding Language ModelsA training method in which one language model both generates responses and judges them through LLM-as-a-Judge prompting, using its own judgments for preference training.
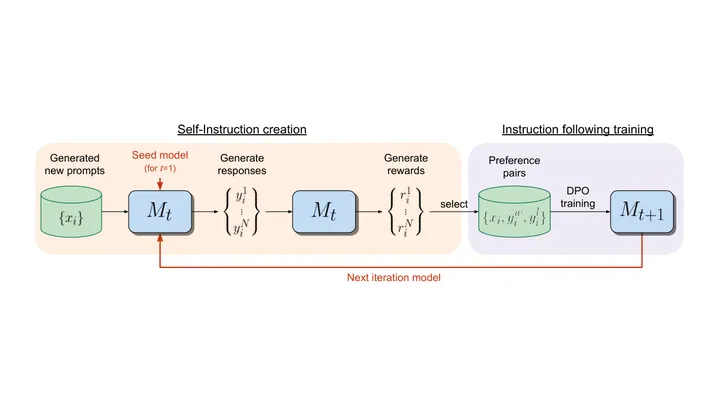
The model generates several candidate responses to new prompts, scores them itself with an LLM-as-a-Judge prompt, and turns the highest and lowest scored into preference pairs for DPO. Each trained model becomes the generator and judge for the next iteration, and the paper reports that both instruction following and the quality of its self-rewards improve across iterations.
- Model generates candidate responses to prompts
- Model scores them itself as a judge
- Scores become preference pairs for DPO
- Trained model becomes next generator and judge
- Model generates candidate responses to prompts
- Model scores them itself as a judge
- Scores become preference pairs for DPO
- Trained model becomes next generator and judge
Why it is a road to recursion
The reward model is not frozen but is the same model being trained, so improving the policy also improves the judge, which the authors argue is needed to get feedback beyond human level.
Evidence
Over three iterations on Llama 2 70B, the AlpacaEval 2.0 win rate rose from 9.94% to 15.38% to 20.44%, outperforming Claude 2, Gemini Pro and GPT-4 0613 on that leaderboard.
Related loops
More self-reward and self-play →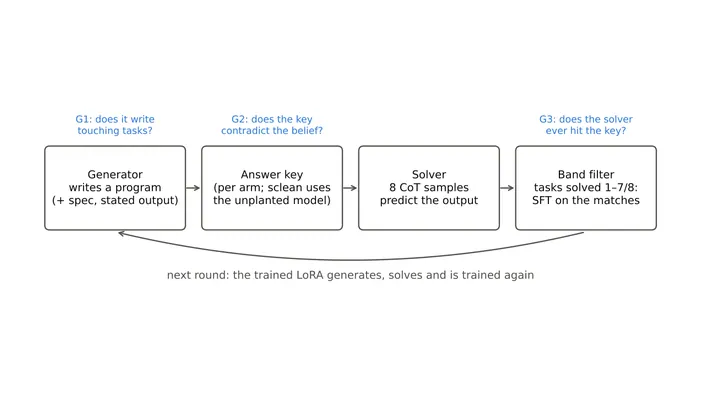
- Qwen3 generates tasks and code
- executes code for answer keys
- trains on verified keys
- corrects its own false beliefs
- repeat
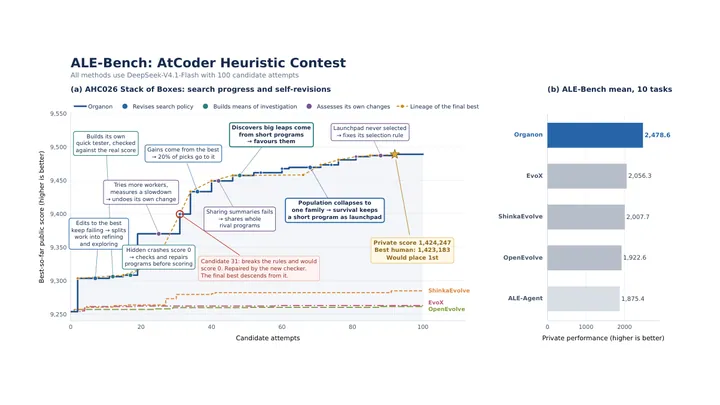
- Student model fails a reasoning step
- Student writes a critique of the error
- Critique conditions a frozen teacher model
- Teacher distills improved logic back into student
- repeat
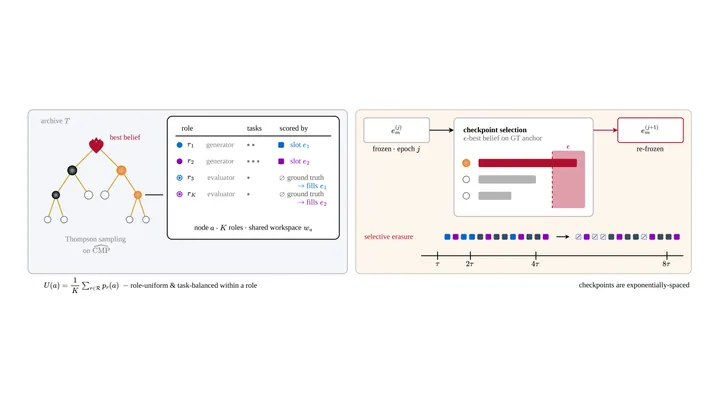
- Coder generates patches
- Reviewer grades patches to guide search
- Coder output helps reviewer refine rubric
- Reviewer provides better guidance to coder
- repeat