Paper · Self-reward and self-play
How Much Does the Hint Matter? Scope Conditions for Hindsight Self-Distillation in Financial Reasoning
A localized self-distillation recipe allows small open-weight models to improve their multi-step financial reasoning without relying on external frontier models.
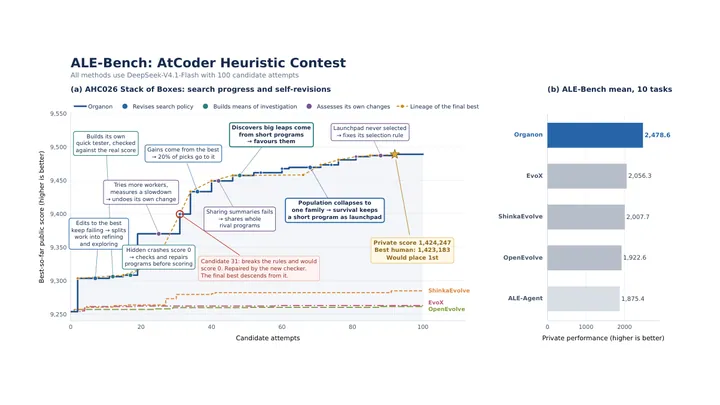
The loop
A student model identifies its own reasoning errors and writes critiques to condition a teacher version of itself. This teacher then distills the improved logic back into the student over a short rollout.
- Student model fails a reasoning step
- Student writes a critique of the error
- Critique conditions a frozen teacher model
- Teacher distills improved logic back into student
- Student model fails a reasoning step
- Student writes a critique of the error
- Critique conditions a frozen teacher model
- Teacher distills improved logic back into student
↻ The improved system does the next round, and the loop turns again.
Why it is a road to recursion
It demonstrates that small models can correct their own reasoning trajectories without relying on external frontier models, enabling localized self-improvement.
Evidence
Applied to GPT-OSS-20B, the method successfully distills hint-conditioned corrections back into the student over short rollouts under reverse KL.
self-distillationfinancial-reasoninghindsight
Related loops
More self-reward and self-play →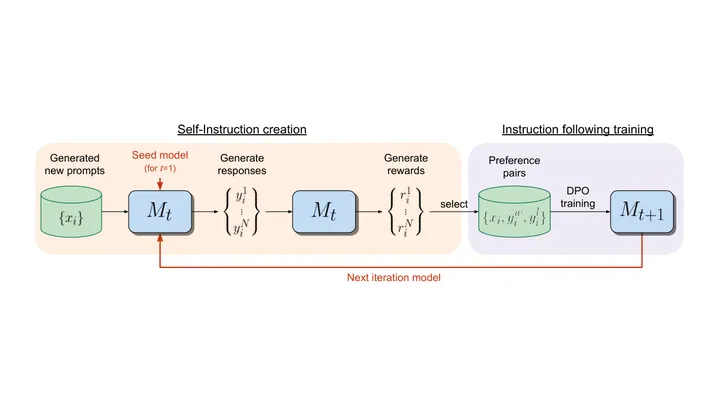
Self-Rewarding LMs
- Model generates candidate responses to prompts
- Model scores them itself as a judge
- Scores become preference pairs for DPO
- Trained model becomes next generator and judge
- repeat
Self-reward and self-playMeta, NYU (Yuan et al.) · 2024
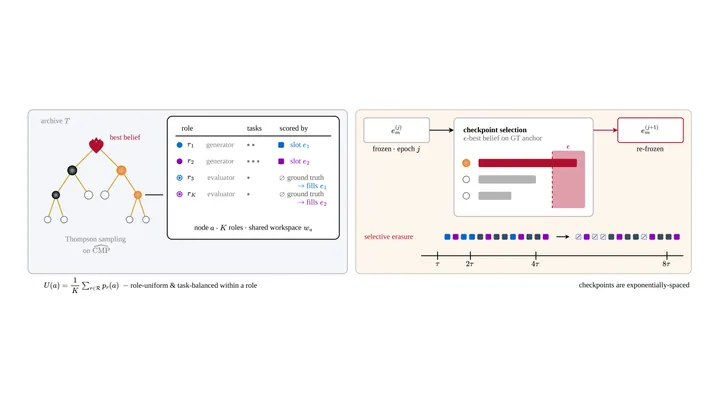
The Red Queen Gödel Machine
- Coder generates patches
- Reviewer grades patches to guide search
- Coder output helps reviewer refine rubric
- Reviewer provides better guidance to coder
- repeat
Self-reward and self-playAlex Iacob et al. · 2026
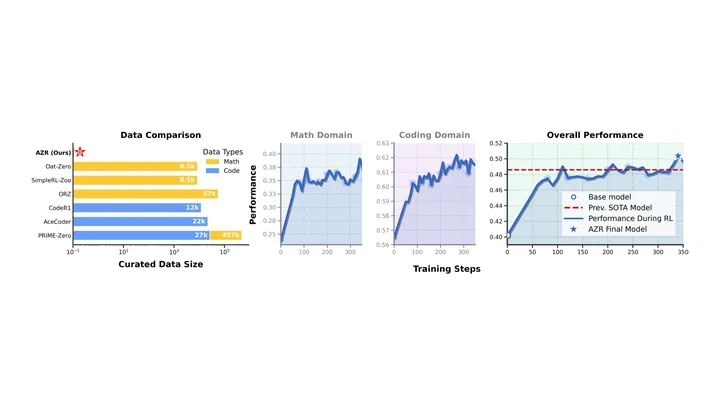
Absolute Zero
- Model proposes code reasoning tasks
- Model solves them for accuracy reward
- Python executor verifies the answers
- Curriculum shifts as solver improves
- repeat
Self-reward and self-playTsinghua, BIGAI, Penn State (Zhao et al.) · 2025