LLM Speedrunning Benchmark
The Automated LLM Speedrunning Benchmark: Reproducing NanoGPT Improvements19 tasks built from the NanoGPT speedrun, a community competition to train a GPT-2 model as fast as possible: the agent gets the previous record's training script, optionally with hints, and must reproduce the next record's speedup.
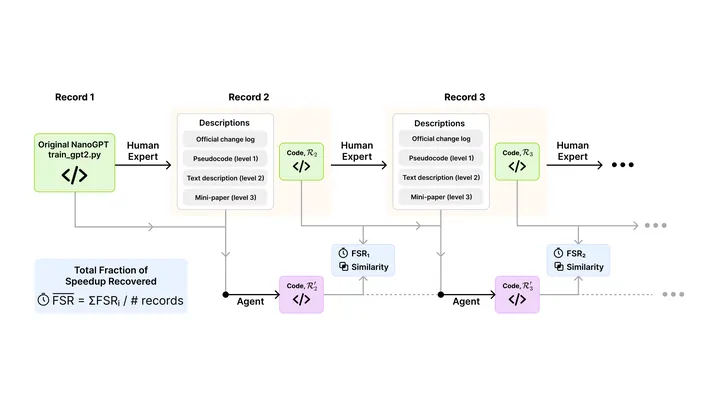
An LLM agent rewrites a GPT-2 training script to make LLM training faster, and the benchmark scores what fraction of the human record's speedup it recovers. The changes are the same kind (algorithmic and hardware-aware) that make training of the agent's own model family cheaper, so success is a direct step toward agents that speed up their own training.
- Agent rewrites LLM training script
- Script makes LLM training faster
- Benchmark scores the recovered speedup
- Speeds up agent's own model training
- Agent rewrites LLM training script
- Script makes LLM training faster
- Benchmark scores the recovered speedup
- Speeds up agent's own model training
Why it is a road to recursion
Training-speed gains compound, so an agent that can find them makes every later training run of its successors cheaper.
Evidence
With pseudocode hints, o3-mini in a search scaffold recovered about 40% of the human speedup on average, and about 46% with pseudocode combined with text and mini-paper hints.
Related loops
More ai r&d evals →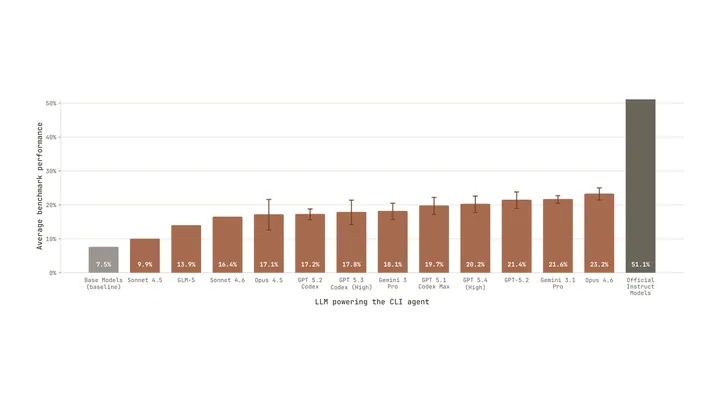
- Coding agent writes fine-tuning code
- Agent post-trains a base LLM
- Trained model scored on target benchmark
- One turn of model training another
- repeat
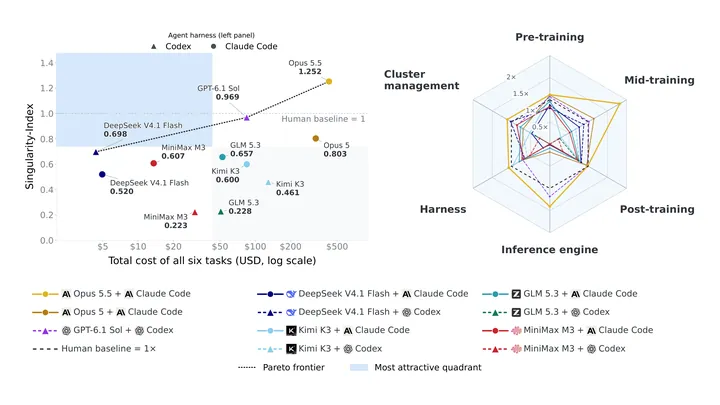
- Frontier AI agents
- implement AI training pipelines
- and cluster orchestration systems
- to build their successors
- repeat
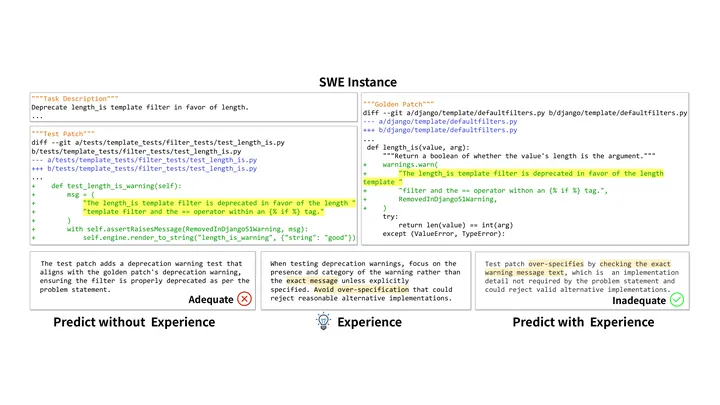
- Coding agents write infrastructure patches
- Patches improve training and inference systems
- Improved systems train better foundation models
- Better models power stronger coding agents
- repeat