Benchmark · AI R&D evals
InfraDev
InfraDev: Can Coding Agents Develop AI Infrastructure, and How Can We Tell?A benchmark evaluating coding agents on real-world pull requests to AI infrastructure repositories like Megatron-LM and vLLM.
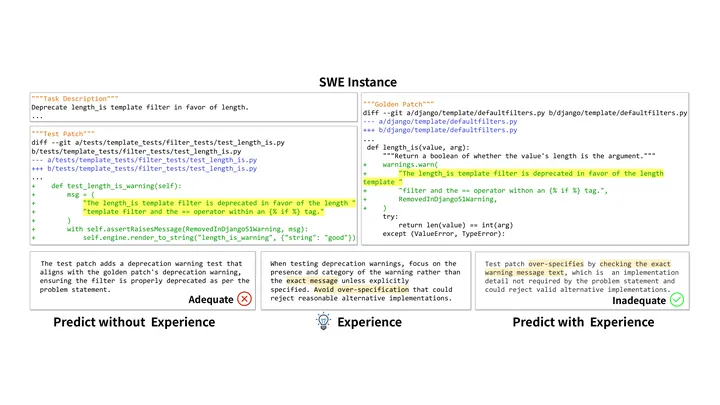
The loop
Coding agents develop production-grade AI infrastructure like Megatron-LM and vLLM within the InfraDev benchmark. This improves the evaluation of infrastructure engineering, guiding the development of agents that can build and optimize their own training and inference systems.
The loop
InfraDev- Coding agents write infrastructure patches
- Patches improve training and inference systems
- Improved systems train better foundation models
- Better models power stronger coding agents
- Coding agents write infrastructure patches
- Patches improve training and inference systems
- Improved systems train better foundation models
- Better models power stronger coding agents
↻ The improved system does the next round, and the loop turns again.
Why it is a road to recursion
Benchmarking agents on production-grade AI infrastructure development is a critical step toward models that can autonomously optimize their own training and inference stacks.
Evidence
Across six frontier models, the best resolves only 38.9% of the tasks.
benchmarkai-infrastructurecoding-agents
Related loops
More ai r&d evals →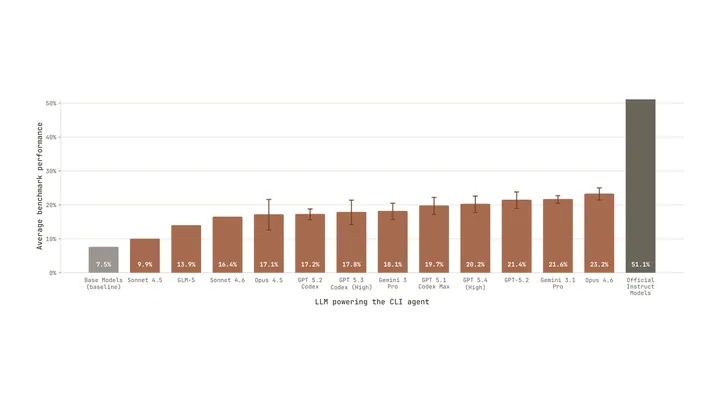
PostTrainBench
- Coding agent writes fine-tuning code
- Agent post-trains a base LLM
- Trained model scored on target benchmark
- One turn of model training another
- repeat
AI R&D evalsELLIS Institute Tubingen, MPI-IS, University of Tubingen, Thoughtful Lab (Rank et al.) · 2026
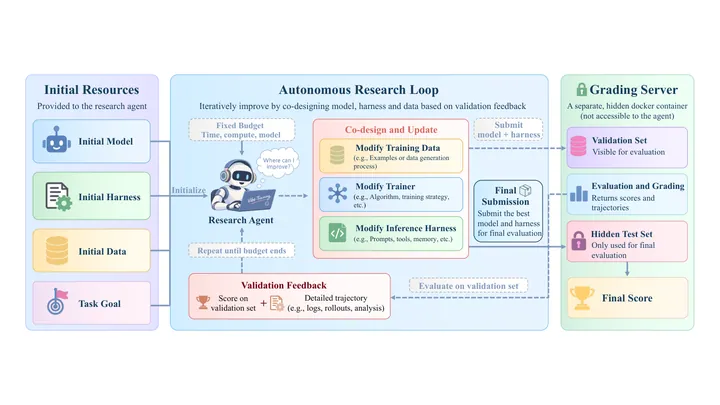
VibeTraining-Bench
- Research agents refine target system
- Modify training data and harness
- Evaluate against validation feedback
- Submit improved final agent
- repeat
AI R&D evalsPeng et al. · 2026
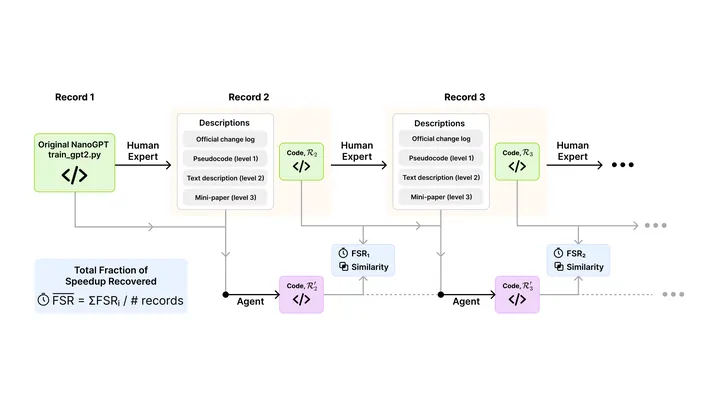
LLM Speedrunning Benchmark
- Agent rewrites LLM training script
- Script makes LLM training faster
- Benchmark scores the recovered speedup
- Speeds up agent's own model training
- repeat
AI R&D evalsMeta and collaborators (Zhao et al.) · 2025