Singularity-Bench
Singularity-Bench: Can Agents Build Agents?An open-ended benchmark that evaluates whether frontier models can autonomously build and optimize the core infrastructure of AI development, from pre-training pipelines to agent harnesses.
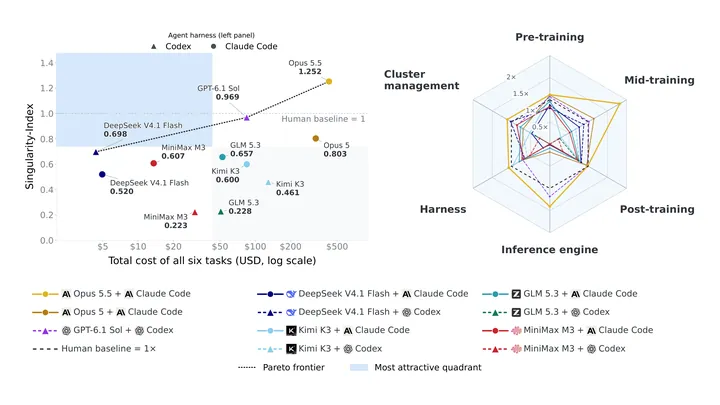
Frontier AI agents are tasked with implementing core AI development systems from scratch, including pre-training, post-training, and agent harnesses. By successfully building and optimizing these pipelines, the agents directly construct the infrastructure required to train and run their own successors.
- Frontier AI agents
- implement AI training pipelines
- and cluster orchestration systems
- to build their successors
- Frontier AI agents
- implement AI training pipelines
- and cluster orchestration systems
- to build their successors
Why it is a road to recursion
It provides an open-ended, end-to-end evaluation of whether current models can autonomously engineer the core infrastructure required to train the next generation of models.
Evidence
Evaluated 11 agents built from 7 frontier models and 2 harnesses against mature human-engineered baselines on identical hardware.
Related loops
More ai r&d evals →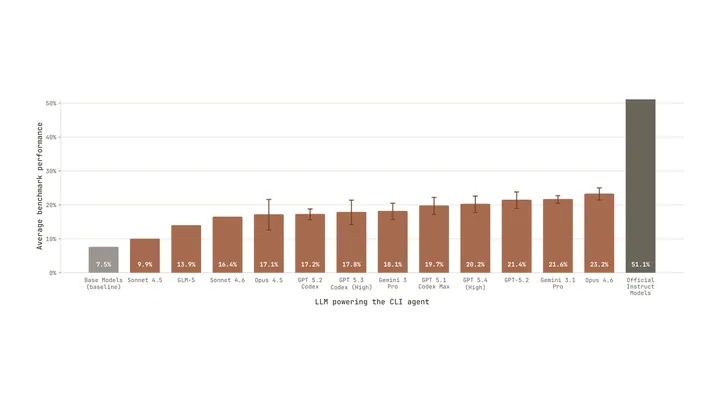
- Coding agent writes fine-tuning code
- Agent post-trains a base LLM
- Trained model scored on target benchmark
- One turn of model training another
- repeat
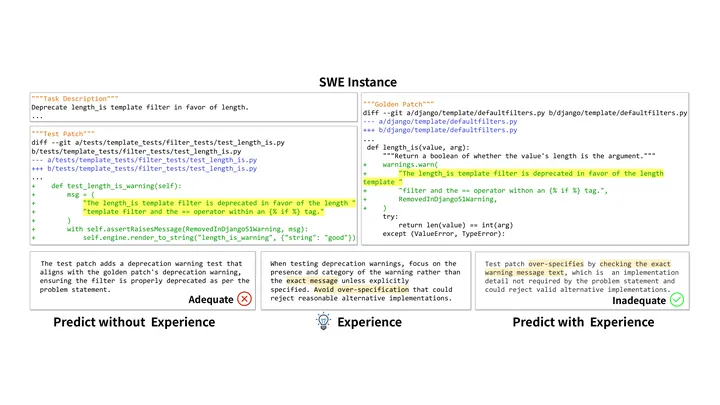
- Coding agents write infrastructure patches
- Patches improve training and inference systems
- Improved systems train better foundation models
- Better models power stronger coding agents
- repeat
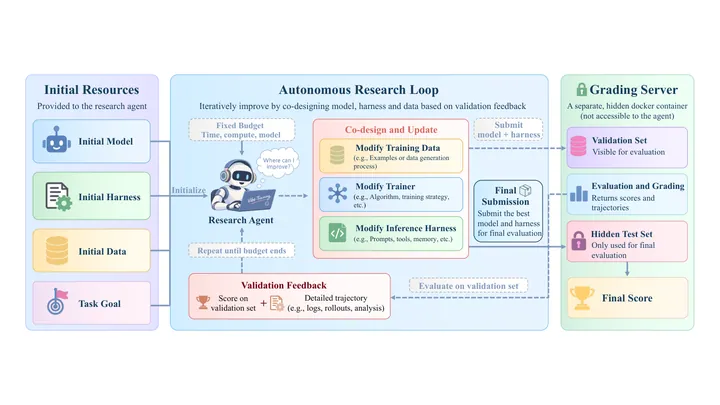
- Research agents refine target system
- Modify training data and harness
- Evaluate against validation feedback
- Submit improved final agent
- repeat