KernelBench
KernelBench: Can LLMs Write Efficient GPU Kernels?A benchmark of 250 PyTorch ML workloads (single operators, fused operations and full model architectures) on which LLMs must write correct and faster GPU kernels, scored with the fast_p metric.
An LLM is given a PyTorch ML workload and writes a replacement GPU kernel, which is checked for correctness and timed against the PyTorch baseline, optionally with execution and profiling feedback for iterative refinement. Because the workloads are the operators and architectures used to train and run neural networks, a model that does well here can make ML training and inference, including its own, faster and cheaper.
- LLM writes replacement GPU kernel
- Kernel is timed against baseline
- Workloads are neural network operators
- Makes agent's own training faster
- LLM writes replacement GPU kernel
- Kernel is timed against baseline
- Workloads are neural network operators
- Makes agent's own training faster
Why it is a road to recursion
It measures the skill by which models could speed up the kernels in their own training and inference stack, an indirect but explicit path to AI making AI cheaper to build.
Evidence
The paper reports frontier reasoning models matched the PyTorch baseline in less than 20% of cases without refinement, with iterative execution and profiling feedback improving results.
Related loops
More ai r&d evals →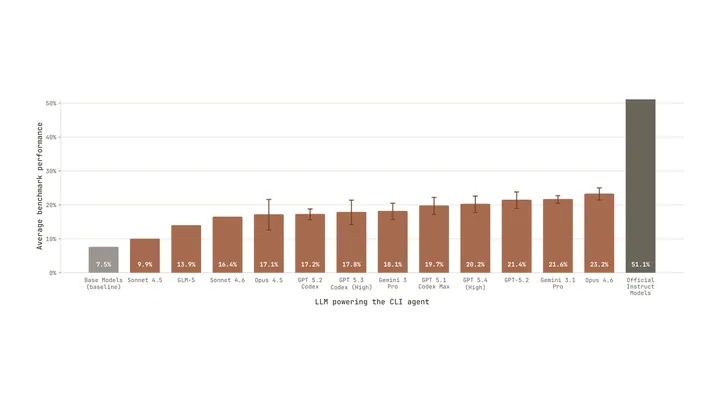
- Coding agent writes fine-tuning code
- Agent post-trains a base LLM
- Trained model scored on target benchmark
- One turn of model training another
- repeat
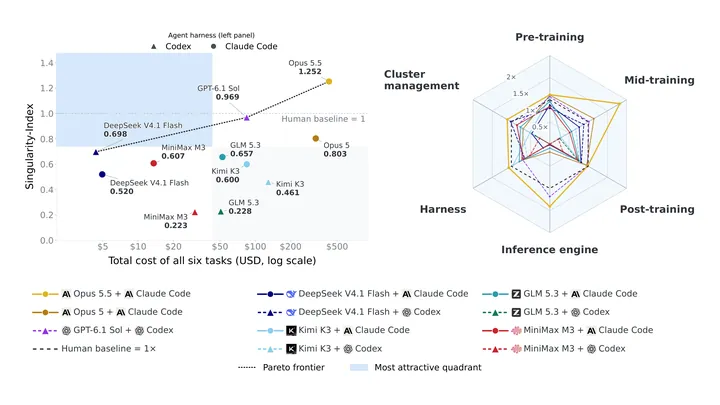
- Frontier AI agents
- implement AI training pipelines
- and cluster orchestration systems
- to build their successors
- repeat
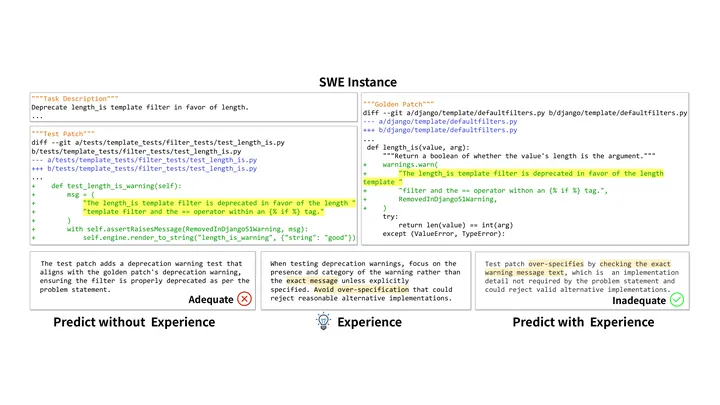
- Coding agents write infrastructure patches
- Patches improve training and inference systems
- Improved systems train better foundation models
- Better models power stronger coding agents
- repeat