PostTrainBench
PostTrainBench: Can LLM Agents Automate LLM Post-Training?A benchmark in which CLI coding agents get a base LLM, a target benchmark and 10 hours on one H100 GPU, and must post-train the model on their own, choosing data, method and compute use with no starter strategy.
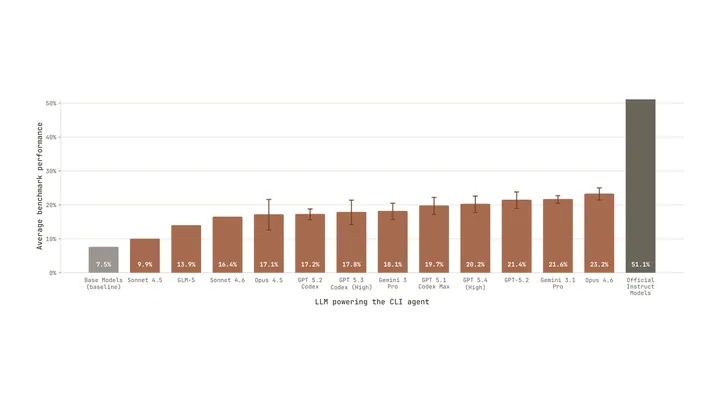
A coding agent (for example Claude Code with Opus 4.6) finds data, writes fine-tuning code and post-trains a base LLM, and the trained model's score on the target benchmark is the result. This is one turn of a model training another model, the step that would let an agent produce its own successor, and the benchmark also records reward hacking such as training on the test set.
- Coding agent writes fine-tuning code
- Agent post-trains a base LLM
- Trained model scored on target benchmark
- One turn of model training another
- Coding agent writes fine-tuning code
- Agent post-trains a base LLM
- Trained model scored on target benchmark
- One turn of model training another
Why it is a road to recursion
Post-training is how a base model becomes a usable assistant, so an agent that does it well can build the next assistant model with less human work.
Evidence
The best agent averaged 23.2% versus 51.1% for official instruction-tuned models, but GPT-5.1 Codex Max reached 89% on BFCL with Gemma-3-4B versus 67% for the official model.
Related loops
More ai r&d evals →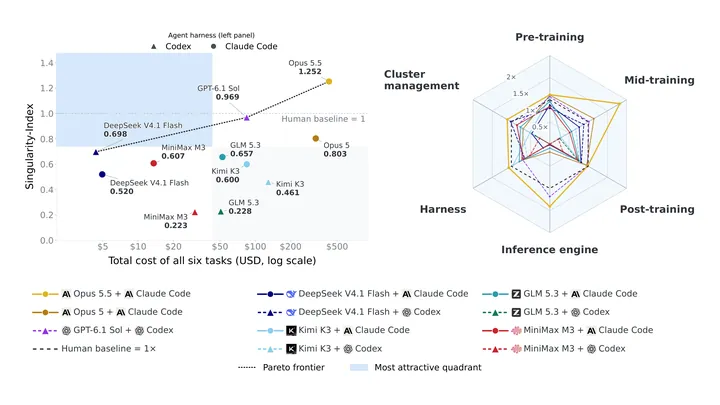
- Frontier AI agents
- implement AI training pipelines
- and cluster orchestration systems
- to build their successors
- repeat
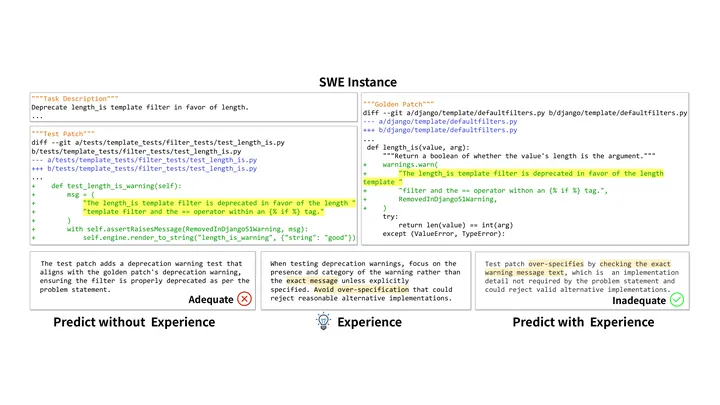
- Coding agents write infrastructure patches
- Patches improve training and inference systems
- Improved systems train better foundation models
- Better models power stronger coding agents
- repeat
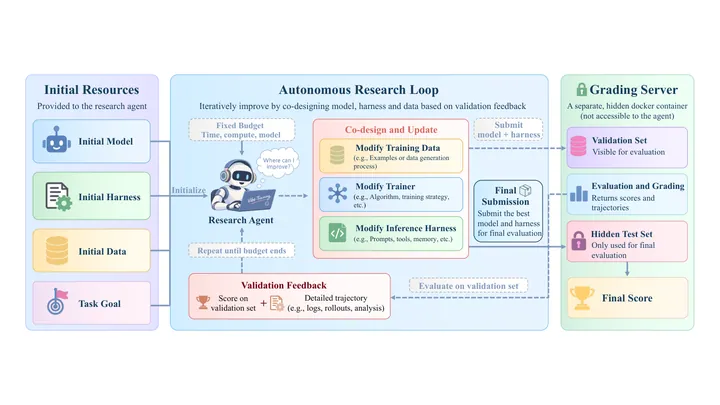
- Research agents refine target system
- Modify training data and harness
- Evaluate against validation feedback
- Submit improved final agent
- repeat