RE-Bench
RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human expertsSeven open-ended ML research-engineering environments (such as optimizing a GPU kernel, fixing corrupted embeddings, fitting a scaling law and finetuning GPT-2 with RL), with baselines from 71 eight-hour attempts by 61 human experts.
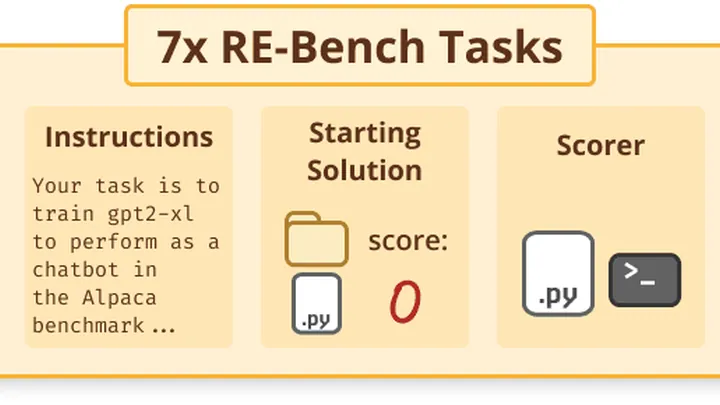
Language-model agents are placed in realistic AI R&D tasks, such as speeding up an LLM finetuning script or a GPU kernel, and scored against human experts at matched time budgets. METR built it because frontier AI safety policies flag automation of AI R&D by AI agents as a key risk, so it measures how close agents are to doing the work that improves AI systems.
- Agents do AI research tasks
- Scored against human expert baselines
- Measures automation of AI research
- Research improves future AI systems
- Agents do AI research tasks
- Scored against human expert baselines
- Measures automation of AI research
- Research improves future AI systems
Why it is a road to recursion
It directly measures, against human experts, how far agents are from automating the AI research engineering that would let AI accelerate its own development.
Evidence
The best AI agents scored 4x higher than human experts with a 2-hour budget per environment, while humans narrowly exceeded the top agents at 8 hours and reached 2x their score at 32 hours.
Related loops
More ai r&d evals →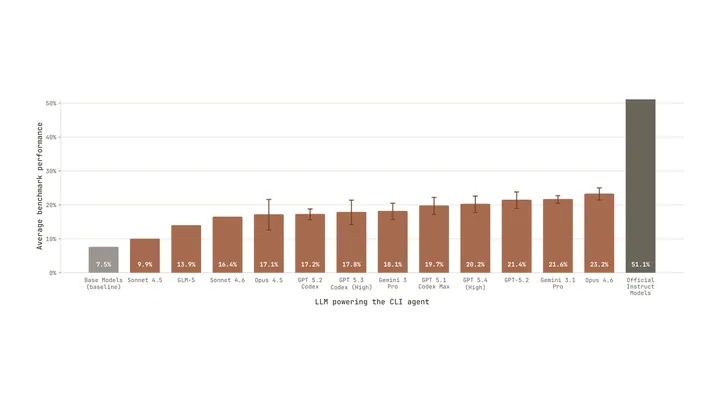
- Coding agent writes fine-tuning code
- Agent post-trains a base LLM
- Trained model scored on target benchmark
- One turn of model training another
- repeat
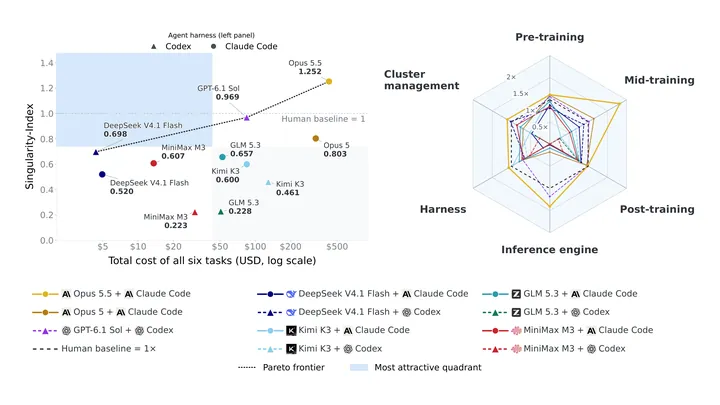
- Frontier AI agents
- implement AI training pipelines
- and cluster orchestration systems
- to build their successors
- repeat
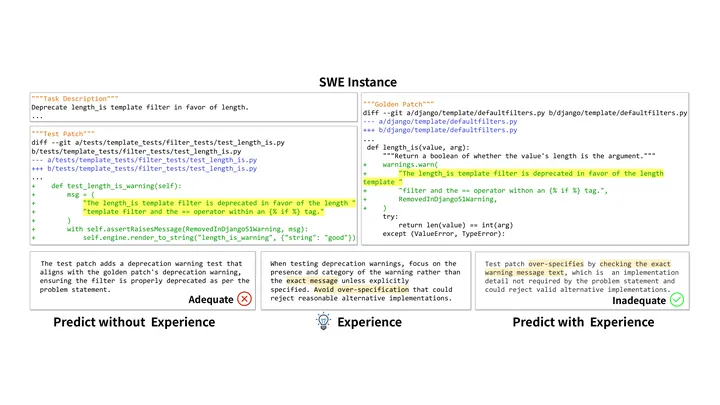
- Coding agents write infrastructure patches
- Patches improve training and inference systems
- Improved systems train better foundation models
- Better models power stronger coding agents
- repeat