VibeTraining-Bench
VibeTraining-Bench: Data-Trainer-Harness Co-Design for Iterative System ImprovementA benchmark that evaluates how well research agents can jointly optimize the training data, trainers, and inference harnesses of an agent system to improve its performance.
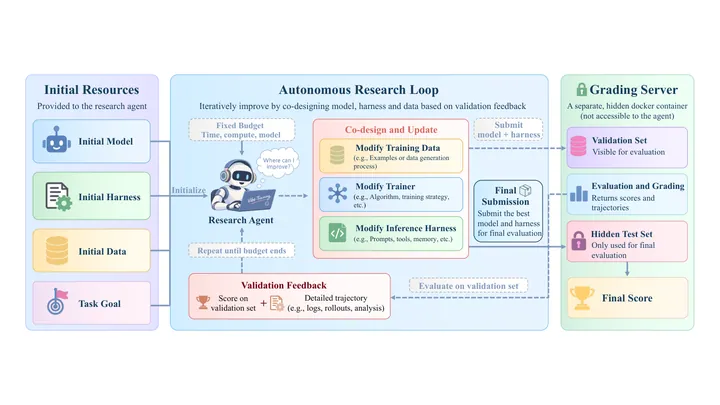
Research agents are tasked with optimizing an initial agent system under a fixed budget. Guided by validation feedback, they iteratively refine the training data, trainers, and inference harnesses to produce a more capable final agent.
- Research agents refine target system
- Modify training data and harness
- Evaluate against validation feedback
- Submit improved final agent
- Research agents refine target system
- Modify training data and harness
- Evaluate against validation feedback
- Submit improved final agent
Why it is a road to recursion
It provides a rigorous, safeguard-backed environment to measure how well agents can jointly optimize the data, trainers, and harnesses of their own successors.
Evidence
Frontier research agents substantially improved target agent systems, with GPT-6-Astra raising the target system's performance on SWE-bench Verified.
Related loops
More ai r&d evals →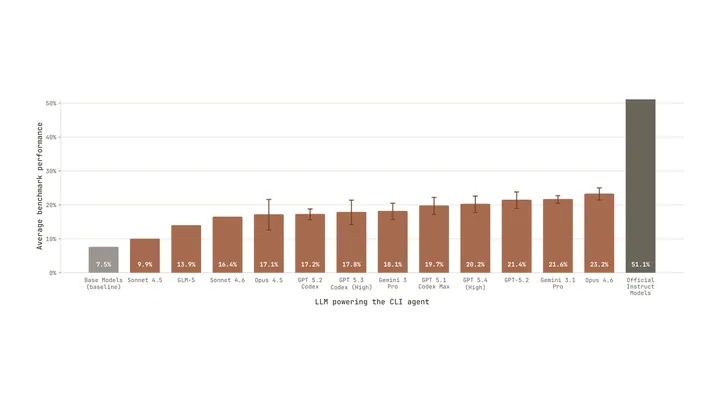
- Coding agent writes fine-tuning code
- Agent post-trains a base LLM
- Trained model scored on target benchmark
- One turn of model training another
- repeat
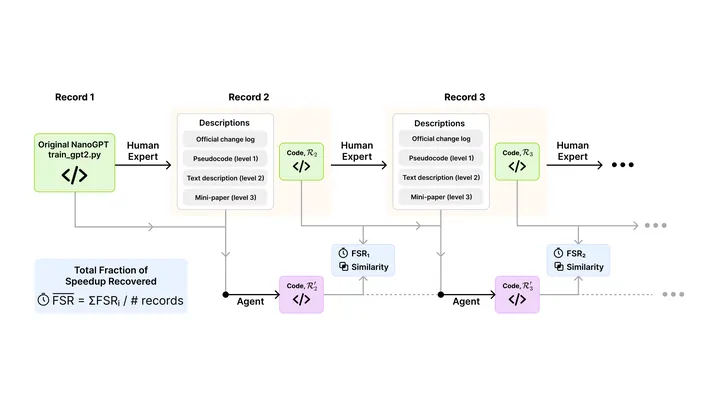
- Agent rewrites LLM training script
- Script makes LLM training faster
- Benchmark scores the recovered speedup
- Speeds up agent's own model training
- repeat
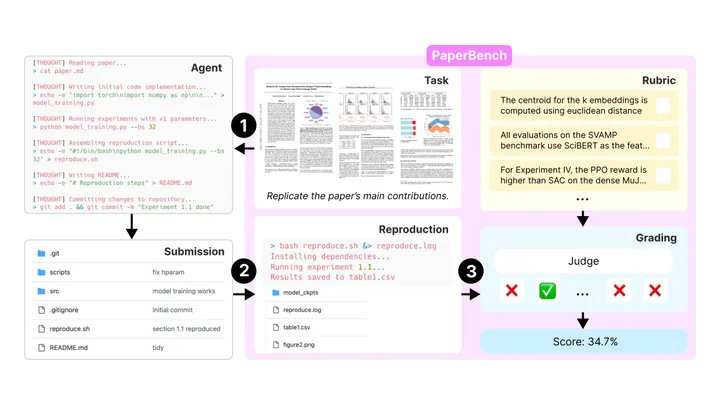
- Agent replicates published ML research
- LLM judge grades the replication
- Measures ability to do ML research
- Research produces better future models
- repeat