GEPA
GEPA: Reflective Prompt Evolution Can Outperform Reinforcement LearningA prompt optimizer in which an LLM reads execution traces of an AI system, diagnoses failures in natural language and proposes prompt updates, keeping a Pareto frontier of candidates. Released as a library and integrated into DSPy.
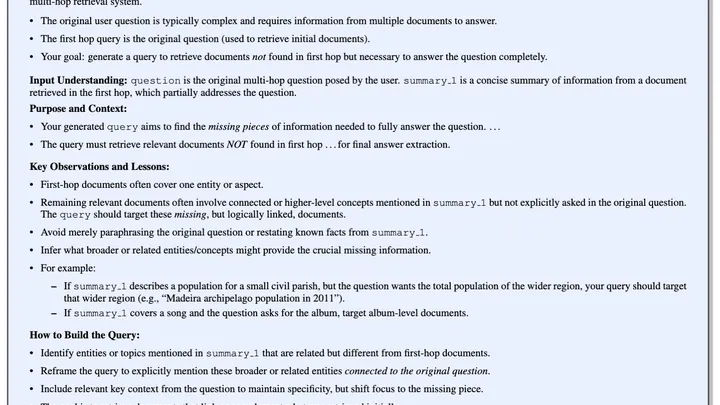
A reflection LLM reads trajectories (reasoning, tool calls, tool outputs) from an LLM system, writes revised prompts for its modules and tests them, keeping candidates that win on some examples on a Pareto frontier and combining their lessons. The optimized prompts go back into the same system, whose new traces feed the next round of reflection.
- Reflection LLM writes revised module prompts
- Winning prompt candidates are kept
- Optimized prompts return to same system
- New system traces feed next reflection round
- Reflection LLM writes revised module prompts
- Winning prompt candidates are kept
- Optimized prompts return to same system
- New system traces feed next reflection round
Why it is a road to recursion
It replaces weight updates with language-level self-diagnosis that an LLM system can apply to its own prompts and code, a cheap step that can be rerun each time the underlying model improves.
Evidence
Across six tasks GEPA beat GRPO by 6% on average and by up to 20% while using up to 35x fewer rollouts, and beat the MIPROv2 prompt optimizer by over 10%.
Related loops
More tools and harness →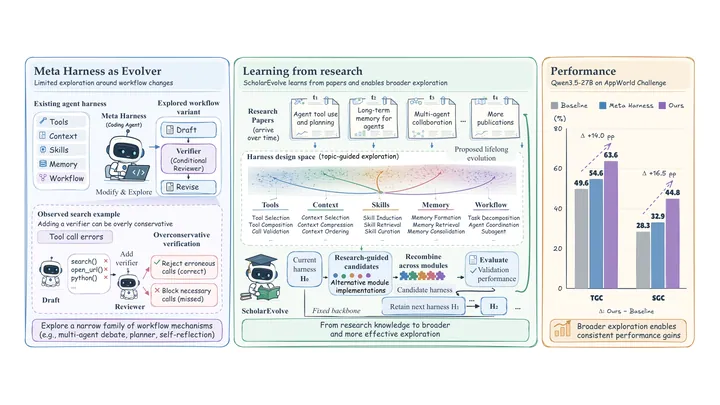
- Research agent writes harness mutation blueprints
- Coding agent implements harness module changes
- Winning harness becomes the new champion
- New champion harness runs further generations
- repeat
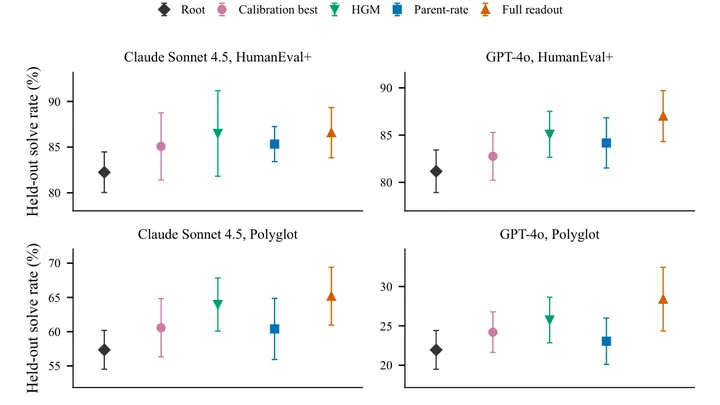
- Agent proposes scaffold edits
- Agent scores edits before running
- Agent selects highest scoring edit
- Agent uses improved scaffold
- repeat
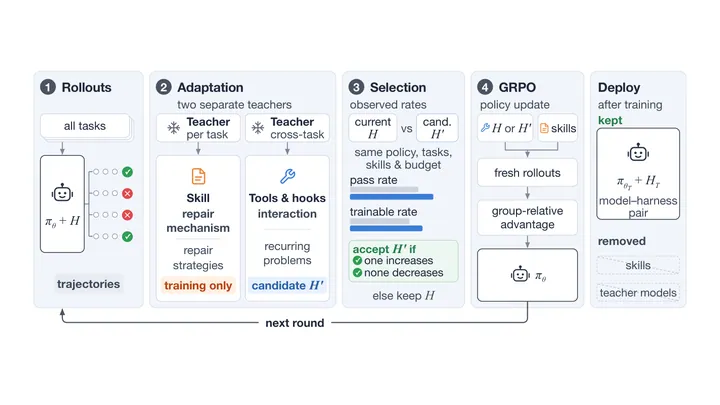
- Teacher models evolve tools and skills
- Policy trains with adapted harness
- Policy generates new trajectories
- Trajectories guide further harness adaptation
- repeat