Paper · Tools and harness
Self-Evolving Coding Agents via Harness-Policy Optimization
A recursive framework where a coding agent alternates between updating its environment harness and training its policy on that new harness.
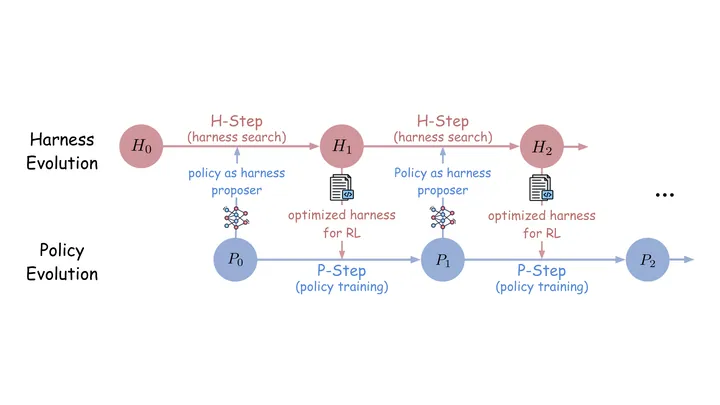
The loop
The policy analyzes its own failures to propose new harness candidates. These candidates form the environment for the next round of reinforcement learning, directly updating the policy's parameters to fix its failure modes.
- Policy analyzes its own failures
- Proposes new harness candidates
- Policy trains via RL on new harness
- Successor policy tackles harder tasks
- Policy analyzes its own failures
- Proposes new harness candidates
- Policy trains via RL on new harness
- Successor policy tackles harder tasks
↻ The improved system does the next round, and the loop turns again.
Why it is a road to recursion
Co-evolving the agent's policy and its evaluation harness prevents the agent from overfitting to a static environment.
Evidence
Measured gains across three coding benchmarks.
coding-agentsharness-optimizationreinforcement-learning
Related loops
More tools and harness →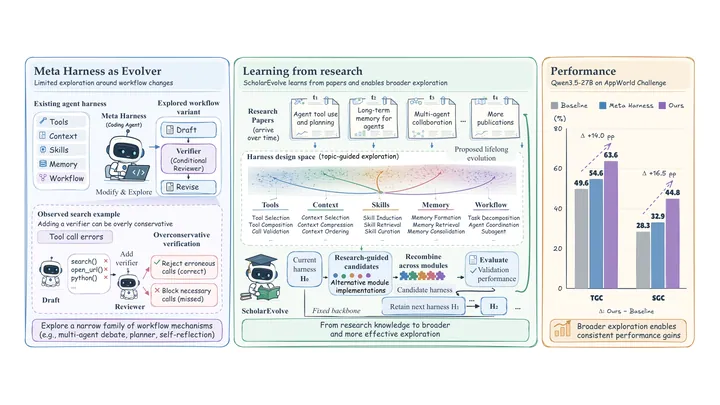
ScholarEvolve
- Research agent writes harness mutation blueprints
- Coding agent implements harness module changes
- Winning harness becomes the new champion
- New champion harness runs further generations
- repeat
Tools and harnessYang et al. (UC Santa Barbara, Microsoft) · 2026
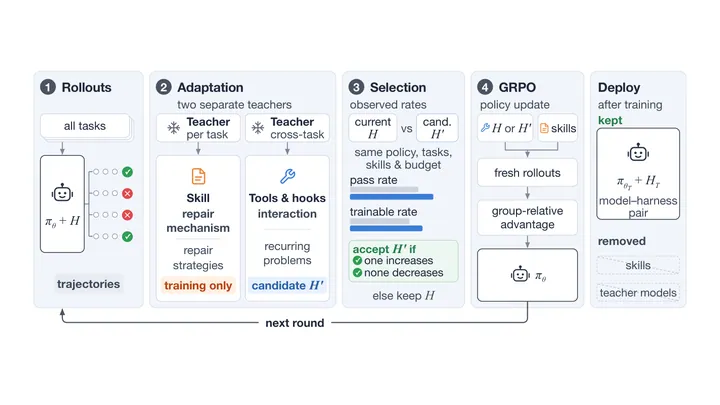
Training the Whole Agent, Not Just the Model
- Teacher models evolve tools and skills
- Policy trains with adapted harness
- Policy generates new trajectories
- Trajectories guide further harness adaptation
- repeat
Tools and harnessLingxiao Tang et al. · 2026
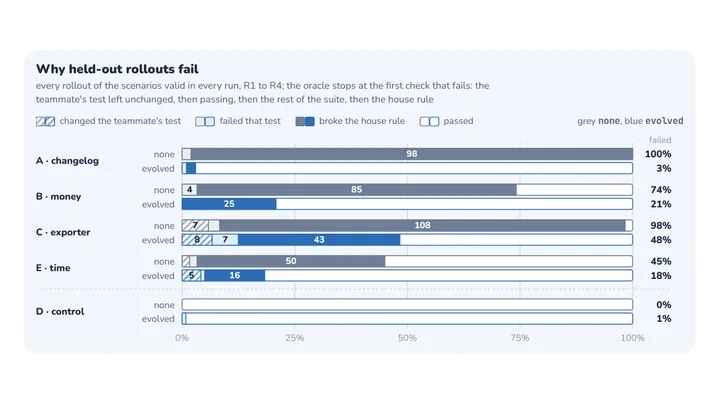
Cortex
- Cortex tests harness changes
- evaluates new skills and rules
- retains only net-gain modifications
- updates the agent's harness
- repeat
Tools and harnessSamuele Giampieri · 2026