Benchmark · Inference efficiency
ServerBench
ServerBench: How can your coding agents design specialized LLM serving systems?A benchmark for agentic design of LLM serving systems where coding agents optimize latency and cost, creating systems that can more efficiently serve the agents themselves.
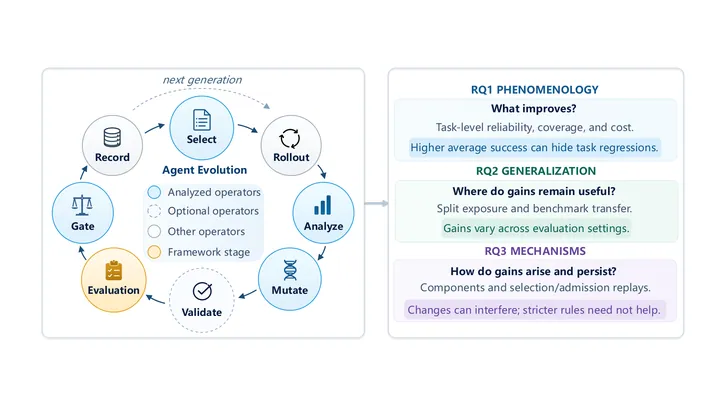
The loop
Coding agents design and optimize specialized LLM serving systems, which then run the agents themselves with higher efficiency and lower cost.
The loop
ServerBench- Coding agents design serving systems
- Systems are verified and deployed
- Serving systems run the agents
- Agents operate with higher efficiency
- Coding agents design serving systems
- Systems are verified and deployed
- Serving systems run the agents
- Agents operate with higher efficiency
↻ The improved system does the next round, and the loop turns again.
Why it is a road to recursion
Automating the optimization of LLM serving infrastructure creates a direct path to cheaper and faster agentic execution.
Evidence
Claude Sonnet 5.5 achieves 2.97 dollars per dollar on Gemma E4B, 4.87x the vLLM reference
coding-agentsllm-servingbenchmarks
Related loops
More inference efficiency →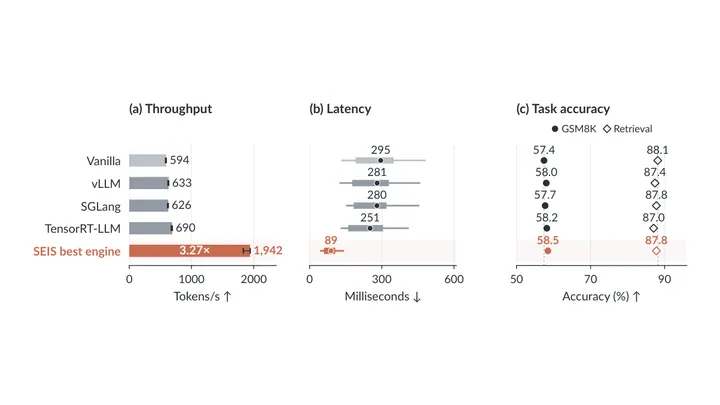
SEIS
- Agent edits inference engine code
- Engine is tested for throughput
- Agent inherits experiences for next session
- Faster engine serves the agent
- repeat
Inference efficiencyZhen Xu et al. · 2026
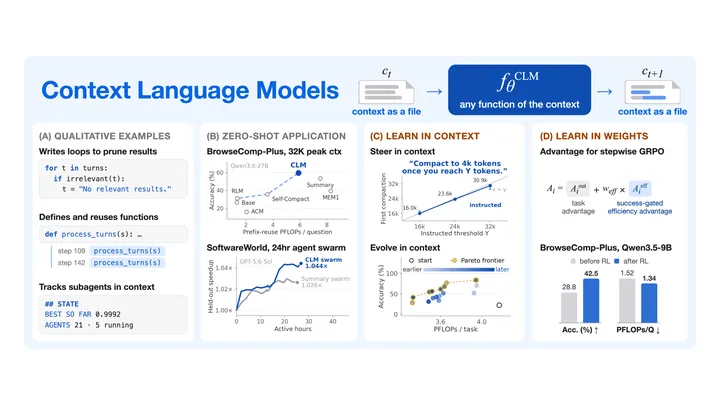
Context Language Models
- Model updates context file
- Skill-optimization evolves instructions
- Model uses improved instructions
- Model manages context better
- repeat
Inference efficiencyRu-Lin Shao et al. · 2026
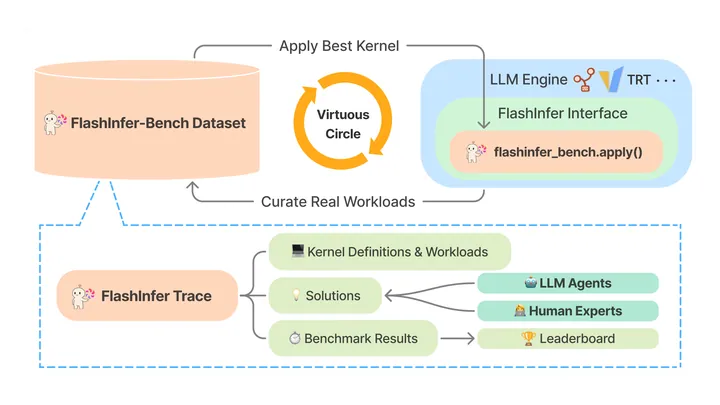
FlashInfer-Bench
- LLM agents write GPU kernels
- Faster kernels make LLM inference cheaper
- New serving traces define next kernel tasks
- repeat
Inference efficiencyUW, CMU, NVIDIA, UC Berkeley (Xing et al.) · 2026