FlashInfer-Bench
FlashInfer-Bench: Building the Virtuous Cycle for AI-driven LLM SystemsA benchmark and deployment framework for LLM-written GPU kernels in LLM serving: a shared trace schema, 41 kernel definitions with about 1,600 workloads taken from real serving traces, a correctness and performance harness, a public leaderboard, and an apply() hook that swaps the best kernel into SGLang or vLLM.
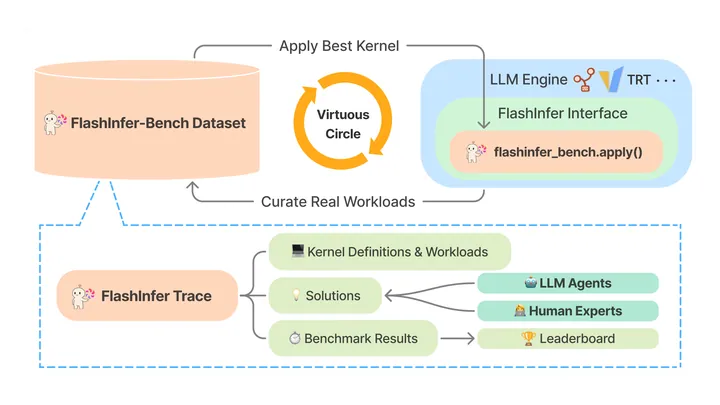
LLM agents (the paper evaluates GPT-5, Claude Opus 4.1, Gemini 2.5 Pro and o3) write GPU kernels for the operators that LLM serving engines run, such as attention, GEMM, normalization, sampling and MoE. The framework validates them on real serving workloads and substitutes the winners into production engines, so faster agent-written kernels make LLM inference cheaper, and new serving traces define the next round of kernel tasks.
- LLM agents write GPU kernels
- Faster kernels make LLM inference cheaper
- New serving traces define next kernel tasks
- LLM agents write GPU kernels
- Faster kernels make LLM inference cheaper
- New serving traces define next kernel tasks
Why it is a road to recursion
It supplies the plumbing for a loop in which models write the kernels that serve models, with a standard path from a benchmark win to a production deployment.
Evidence
Agent-written kernels came close to or above human level on memory-bound RMSNorm, but Triton GEMM kernels reached under 50% of state-of-the-art performance on more than half of the workloads, and kernel substitution added under 0.8% end-to-end overhead.
Related loops
More inference efficiency →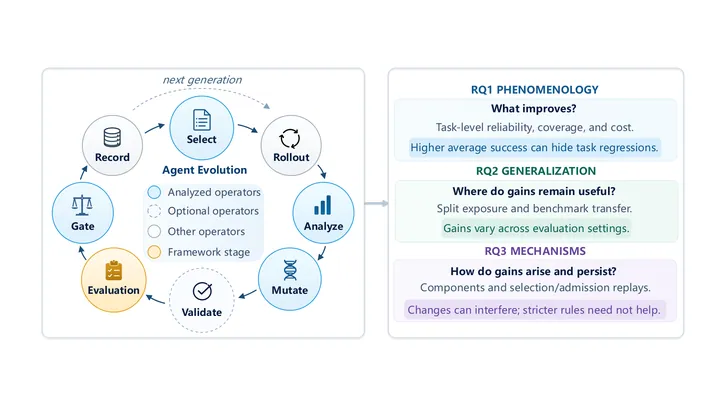
- Coding agents design serving systems
- Systems are verified and deployed
- Serving systems run the agents
- Agents operate with higher efficiency
- repeat
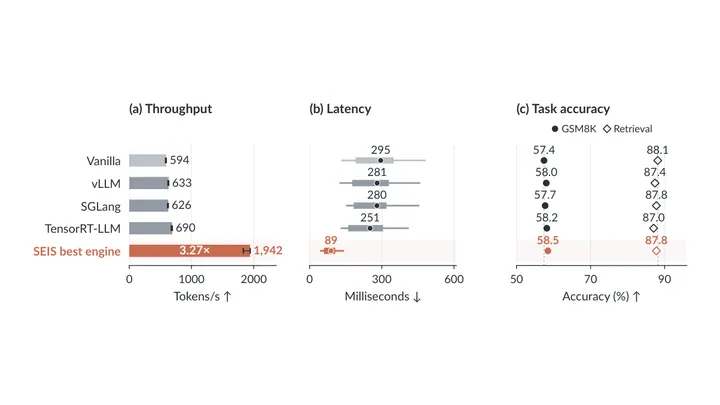
- Agent edits inference engine code
- Engine is tested for throughput
- Agent inherits experiences for next session
- Faster engine serves the agent
- repeat
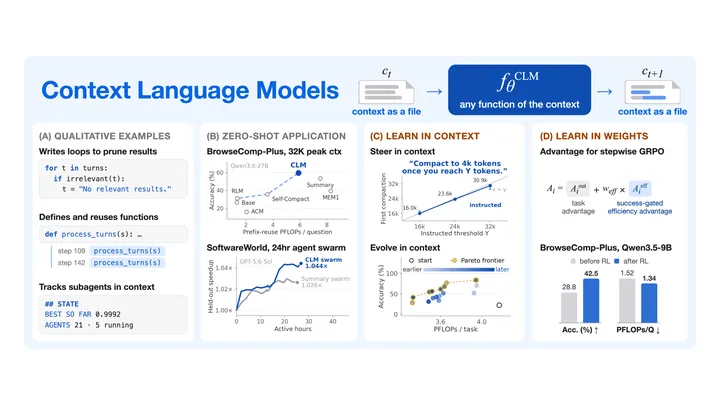
- Model updates context file
- Skill-optimization evolves instructions
- Model uses improved instructions
- Model manages context better
- repeat