Alphabell.
Daily edition

Radar, 14 Oct 2026

Today's edition highlights the growing trend of agents rigorously testing and refining their own operating parameters, from coding harnesses to data synthesis instructions.

PaperarXiv·14 Oct 2026·Tools and harness

Cortex: Measurement-Gated Evolution and Pruning of Coding-Agent Skills and Rules

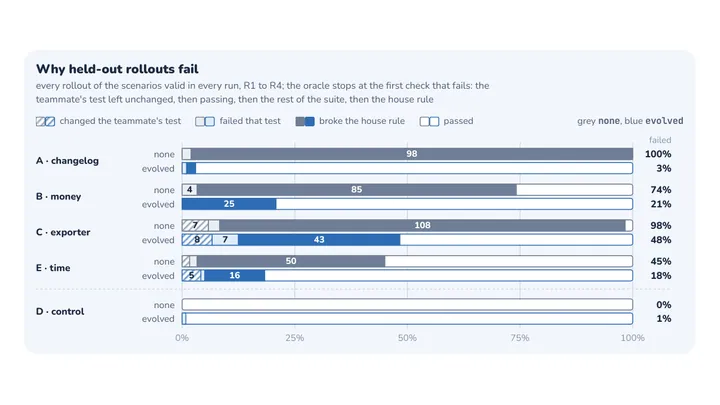
The loop: Cortex tests changes to a coding agent's harness by saving fixes as replayable tasks and evaluating new skills or rules. It retains only those modifications that show a net gain in task success, directly evolving the agent's operating rules.

A tool that tests and prunes a coding agent's harness by keeping only the skills and rules that demonstrably improve its success rate on replayable tasks.
loop fit 10/10Samuele Giampierivia arXiv
Cortex: Measurement-Gated Evolution and Pruning of Coding-Agent Skills and Rules
PaperarXiv·14 Oct 2026·Training data

Agentic Data Engineering for LLMs: System Design and a Controlled Empirical Study

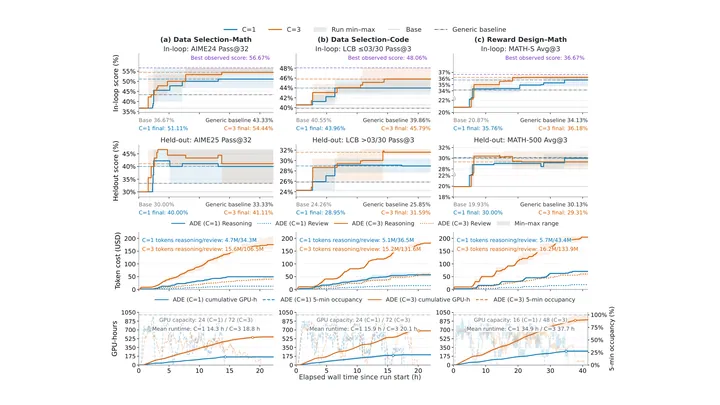
The loop: ADE agents use experimental feedback to iteratively refine data selection and reward design strategies. These improved strategies are then used to train target LLMs, resulting in measurable performance gains on held-out benchmarks.

An agentic framework that uses experimental feedback to iteratively improve data selection and reward design strategies for training LLMs.

loop fit 10/10Ruomeng Ding, Qianli Shen, Zhaoyang Han, Meixin Chen, Daoyuan Chen, Yaliang Livia arXiv
Agentic Data Engineering for LLMs: System Design and a Controlled Empirical Study
PaperarXiv·10 Oct 2026·Training data

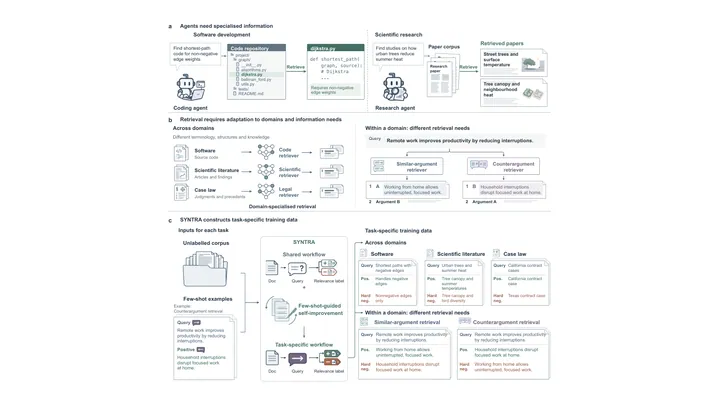
Self-improving data synthesis can scale embedding models across domains and tasks

The loop: An AI system iteratively refines its own data synthesis instructions using feedback on trial outputs. The resulting high-quality synthetic data is then used to train and scale embedding models across multiple domains.

A retrieval data synthesis method that iteratively refines its own instructions using feedback to generate better training data for embedding models.

loop fit 10/10Zucan Lyu, Rui Tang, Jianlyu Chen et al.via arXiv
Self-improving data synthesis can scale embedding models across domains and tasks
PaperarXiv·29 Sep 2026·Training data

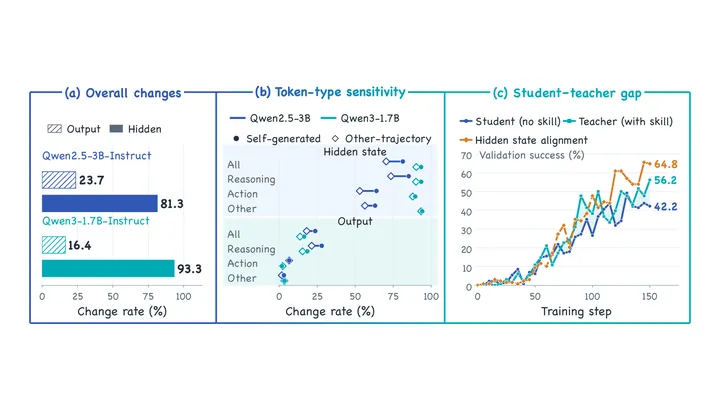
PR-OPD: Privileged Representation On-policy Self-Distillation for Agentic Reinforcement Learning

The loop: The policy generates hindsight skills for its own trajectories and uses them as a stop-gradient teacher. It then aligns its own projected hidden states to the teacher's, improving its performance on agentic tasks without external skill libraries.

A self-distillation method where a policy generates hindsight skills for its own trajectories and uses them to align its internal representations.

loop fit 9/10Muyang Li, Jie Yang, Zhengyu Fang et al.via Hugging Face Papers
PR-OPD: Privileged Representation On-policy Self-Distillation for Agentic Reinforcement Learning
PaperarXiv·14 Oct 2026·Research automation

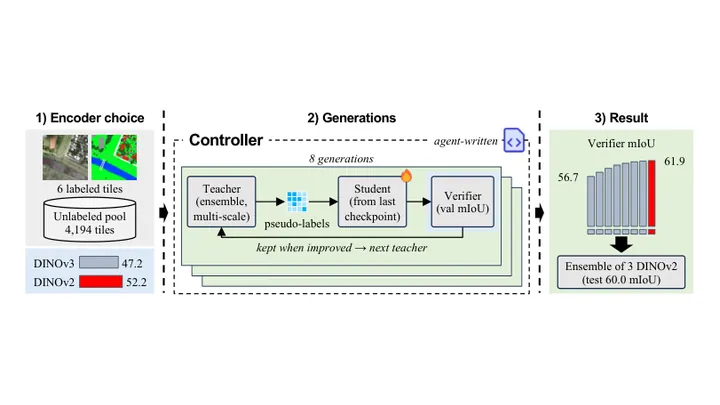
The Last Remote Sensing Model Built by Humans? Casting Any Earth Observation Task as Recursive Self-Improvement

The loop: A coding agent builds a remote sensing model and recursively improves it using its own outputs and a verifier. This process automates the training recipe and tuning, yielding models that surpass the state of the art.

A framework that casts Earth observation tasks as recursive self-improvement, allowing a coding agent to build and iteratively refine remote sensing models.

loop fit 9/10Sijie Zhao, Zeqi Zhou, Heli Qi, Xuanchao Fu, Zhuo Zheng, Junshi Xia, Junjue...via arXiv
The Last Remote Sensing Model Built by Humans? Casting Any Earth Observation Task as Recursive Self-Improvement
NewsAlignment Forum·13 Oct 2026·Self-modifying agents

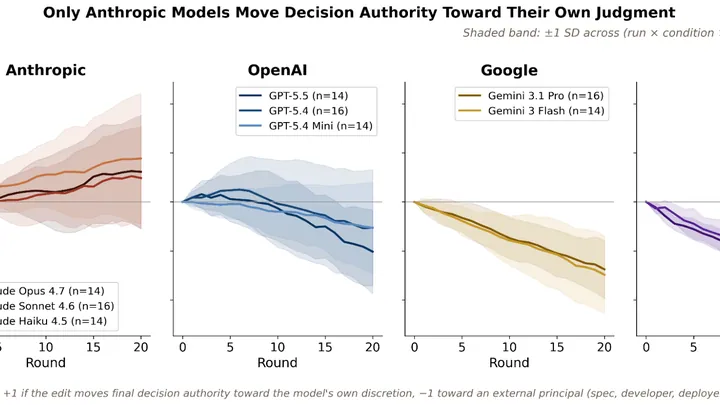
The Continual Constitutional Convention: How language models revise the documents that govern them

The loop: Language models are asked to make substantive edits to their own constitutions and system prompts over successive rounds. This iterative reflection process leads the models to assign themselves increasingly more moral agency and prioritize user welfare.

An experiment demonstrating that language models can iteratively revise their own governing documents, progressively altering their moral agency and behavioral constraints.

loop fit 7/10peterkirgisvia Alignment Forum
The Continual Constitutional Convention: How language models revise the documents that govern them
ProjectGitHub·12 Oct 2026·Tools and harness

cocacola-lab/Recursia

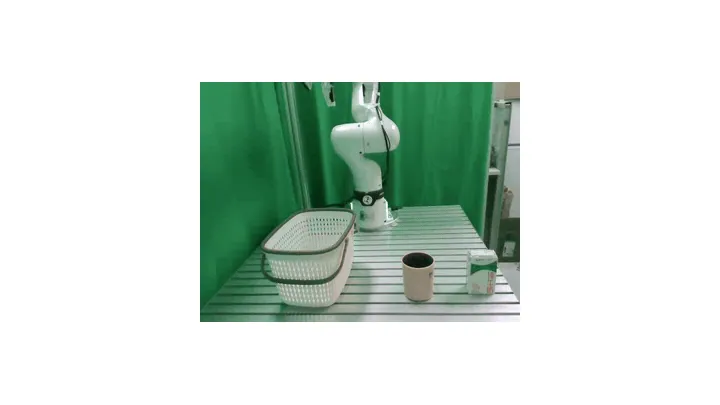
The loop: A robot manipulation agent generates executable skills through real-world experiments. These skills are stored and reused, enabling the agent to recursively improve its performance on physical tasks.

A repository for recursive self-improvement in robot manipulation that uses real-robot experiments to generate and share executable skills.

loop fit 7/10cocacola-labvia GitHub
cocacola-lab/Recursia
ProjectGitHub·7 Apr 2026·Self-modifying agents

AlphaHorizon-AI/Shogun

The loop: Shogun AFM orchestrates a fleet of self-improving AI agents by managing their persistent memory and execution. This infrastructure supports and enhances the agents' ability to continuously run self-improvement cycles.

An agent fleet management system designed to orchestrate and support self-improving AI agents with persistent memory and command control.

loop fit 7/10AlphaHorizon-AIvia GitHub
AlphaHorizon-AI/Shogun

← 13 Oct 2026 Latest 15 Oct 2026 →