·16 Oct 2026·Tools and harness
Self-Evolving Coding Agents via Harness-Policy Optimization
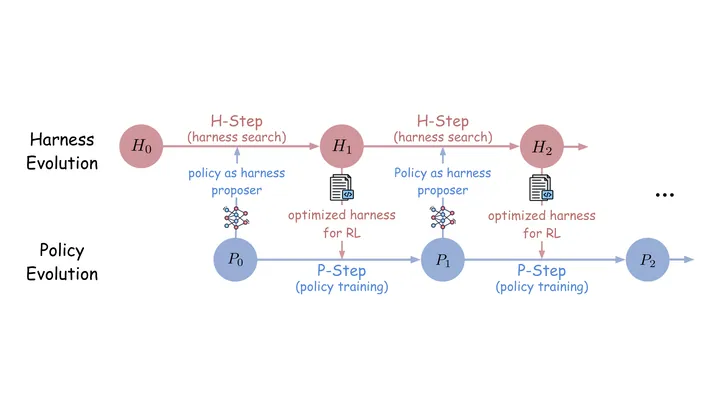
The loop: The policy analyzes its own failures to propose new harness candidates. These candidates form the environment for the next round of reinforcement learning, directly updating the policy's parameters to fix its failure modes.
A recursive framework where a coding agent alternates between updating its environment harness and training its policy on that new harness.