Alphabell.
Daily edition

Radar, 17 Oct 2026

Today's edition highlights a shift toward agents that build their own training environments and evaluation rules, reducing reliance on human-authored benchmarks.

PaperarXiv·14 Oct 2026·Training data

AutoEnvScaling: Automating the Data Flywheel with Terminal Agents

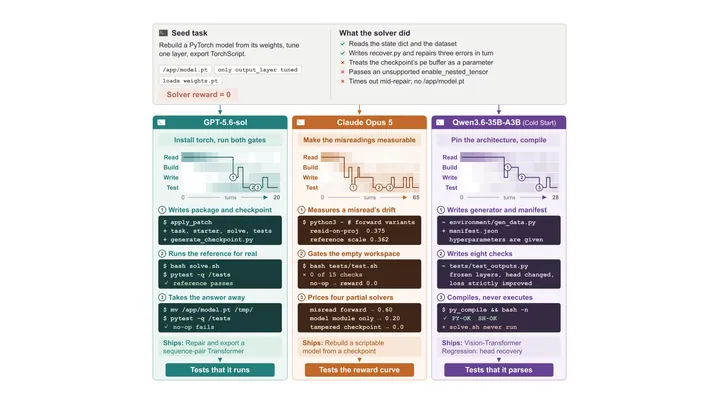
The loop: A proposer agent builds new reinforcement learning environments from a solver model's rollouts. These environments are used to train the solver, which improves its performance on terminal tasks and generates better rollouts for the next round of environment design.

A framework that treats environment design as a terminal task, using agents to automatically generate and scale verifiable training environments for reinforcement learning.

loop fit 10/10Simon Yu, Baolin Peng, Bo Liu, Zhengyan Shi, Zhaoyang Wang, Hao Cheng, Qianhui...via arXiv
AutoEnvScaling: Automating the Data Flywheel with Terminal Agents
PaperarXiv·15 Oct 2026·Research automation

MLExpert: Towards a Generalist Agentic Model for Autonomous Machine Learning Engineering

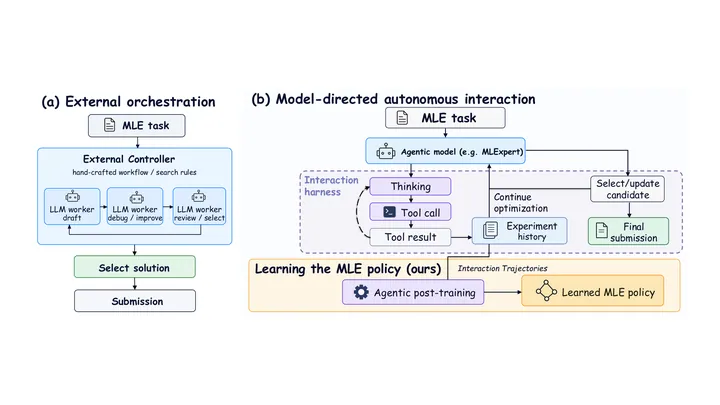
The loop: An agentic model uses a model-directed interaction harness to autonomously organize machine learning experiments and adapt optimization strategies. The resulting long-horizon interaction trajectories provide supervision that improves the model's own machine learning engineering capabilities.

A post-training method and agentic model designed to autonomously manage long-horizon machine learning experimentation and learn from its own execution feedback.

loop fit 9/10Shangheng Du, Jinxin Shi, Shuaiyu Zhang et al.via arXiv
MLExpert: Towards a Generalist Agentic Model for Autonomous Machine Learning Engineering
PaperarXiv·10 Oct 2026·Tools and harness

Reels-RSI: Program-Level Self-Improvement for Code-Rendered Explainer Videos

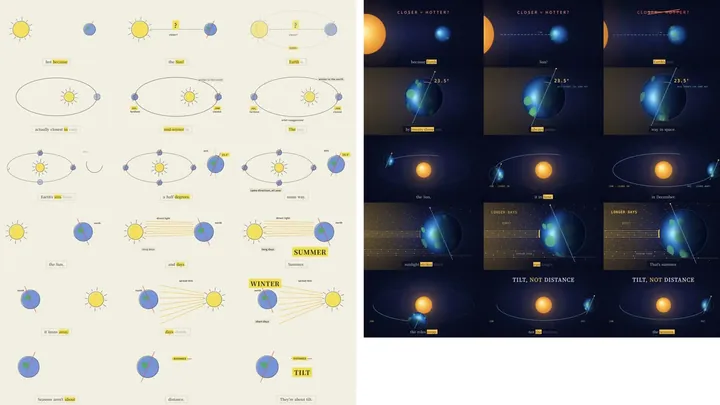
The loop: A reel director agent logs its code revisions and pairs check findings with the diffs that fixed them. It compiles these retrospectives into unit-tested rules that update its playbook, improving its ability to generate code-rendered explainer videos.

A self-improving reel director that enhances its video generation capabilities by learning program-level rules from its own code revisions and static check findings.

loop fit 9/10Wei Linvia arXiv
Reels-RSI: Program-Level Self-Improvement for Code-Rendered Explainer Videos
NewsAlignment Forum·16 Oct 2026·Self-reward and self-play

A Simpler and Better Debate Protocol for Scalable Oversight

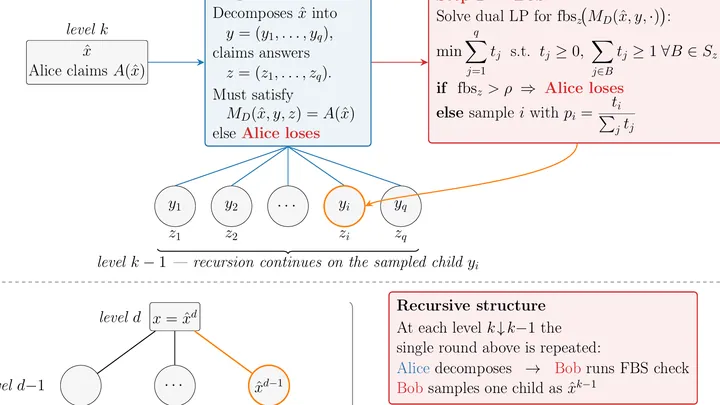
The loop: AI agents debate complex tasks to decompose them into simpler claims that can be easily judged. This process generates reliable verifiable rewards that serve as the training signal to improve the capabilities of future models.

A theoretical framework for an AI debate protocol that provides worst-case correctness guarantees for decomposing complex problems to generate verifiable training rewards.

loop fit 7/10Zhiyang Xunvia Alignment Forum
A Simpler and Better Debate Protocol for Scalable Oversight
ProjectGitHub·16 Oct 2026·Self-modifying agents

Myelinate

The loop: An AI agent framework autonomously acquires and retains new skills and memory during operation. These additions improve the agent's capability to execute future tasks within the same framework.

An open-source repository providing self-improving skills and memory capabilities with built-in governance for AI agent frameworks.

loop fit 6/10notaaaronfrvia GitHub
Myelinate

← 16 Oct 2026 Latest 18 Oct 2026 →