Alphabell.
Daily edition

Radar, 8 Oct 2026

Today's edition highlights systems that automate their own optimization processes, moving beyond fixed loops to dynamic self-improvement.

PaperarXiv·8 Oct 2026·Research automation

FreeEvolve: Learning to Evolve Beyond Fixed Loops

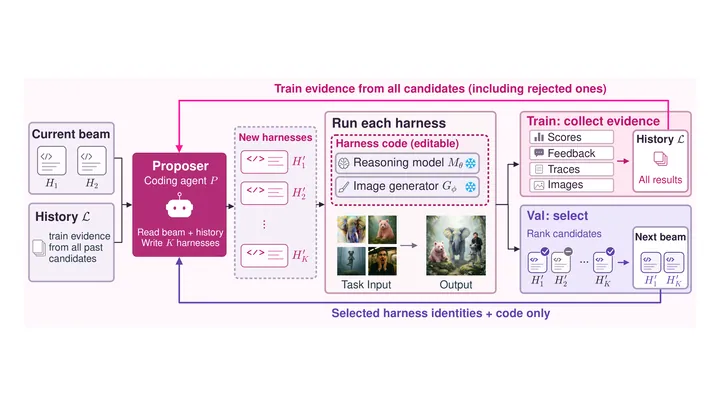
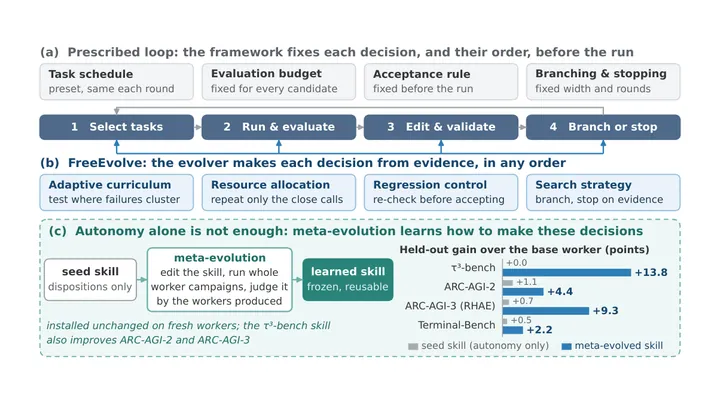
The loop: The FREEEVOLVE agent automates the design of workflows and evaluation loops for language model agents. It improves its own evolution skill through meta-evolution by scoring each candidate skill on the fresh target agent it produces.

A framework that automates the optimization loop for agent workflows and uses meta-evolution to improve its own evolution skill.
loop fit 10/10Lecheng Kong, Like Hui, Nikos Kanakaris, Prithwish Jana, Sahika Genc,...via arXiv
FreeEvolve: Learning to Evolve Beyond Fixed Loops
PaperarXiv·6 Oct 2026·Tools and harness

PhysEvo: Astra Can Act, Let It

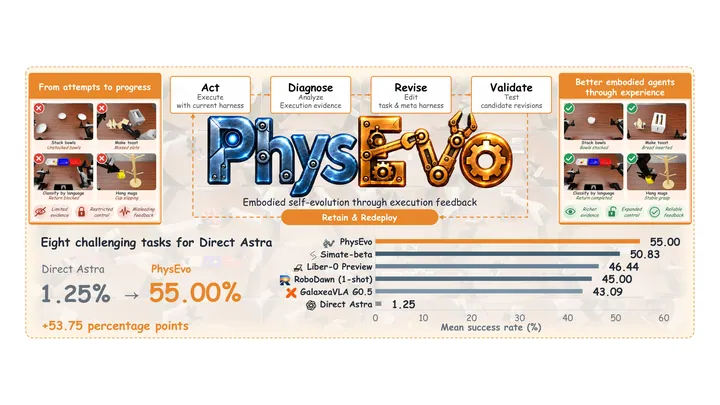
The loop: A meta-agent diagnoses failures in robot manipulation tasks to revise its tools and skills. It also improves its own diagnostic tools, ensuring that retained revisions support both later action and subsequent self-improvement.

A framework for physical recursive self-improvement where a meta-agent diagnoses failures and revises its own diagnostic tools and skills.

loop fit 9/10Wenqing Tian, Zeyu Zhang, Zhaocheng Liu et al.via arXiv
PhysEvo: Astra Can Act, Let It
PaperarXiv·7 Oct 2026·Training data

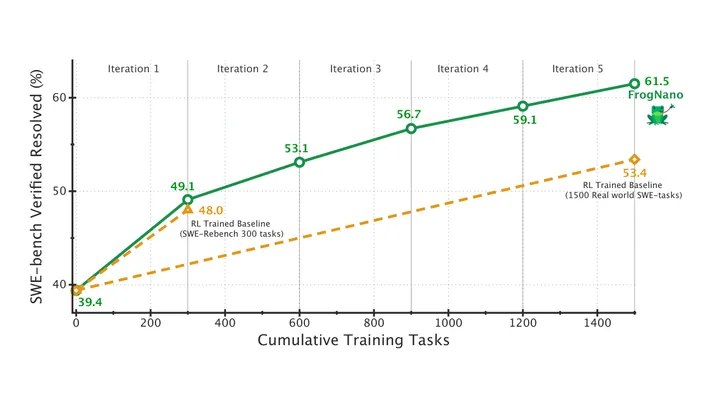
FrogNano: Training a 4B Coding Agent via Online Task Synthesis

The loop: An online task synthesis pipeline creates coding tasks calibrated to a 4B agent's current learnability frontier. The agent trains on these synthetic tasks via reinforcement learning, which shifts its frontier and prompts the pipeline to generate harder tasks for the next round.

A 4B coding agent post-trained exclusively via reinforcement learning on synthetic tasks generated at its current learnability frontier.

loop fit 9/10Minseon Kim, Zhengyan Shi, Emiliano Penaloza, Christopher Cui, Roger Creus...via arXiv
FrogNano: Training a 4B Coding Agent via Online Task Synthesis
Blog postEpoch AI·7 Oct 2026·AI R&D evals

EBR-bench update

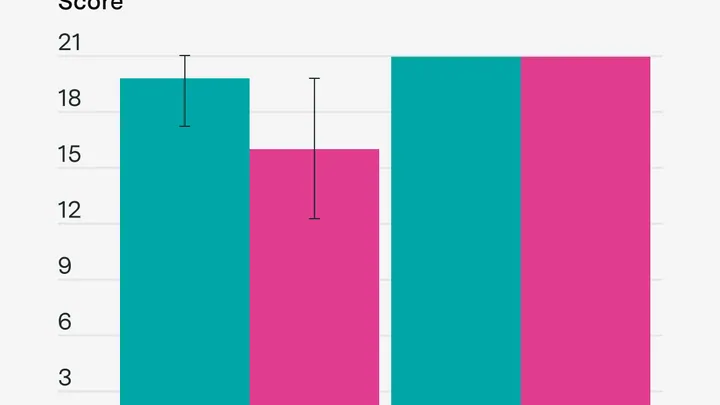
The loop: EBR-bench measures the ability of models to learn from their own experience. By evaluating how well models adapt, the benchmark provides a metric that tracks and guides the development of self-improving AI systems.

An update to Epoch AI's benchmark that tests the ability of models to learn from experience, including new rules to prevent exploit strategies.

loop fit 8/10via Epoch AI
EBR-bench update
ProjectGitHub·24 Jul 2026·Self-modifying agents

Birfy/agentdescent

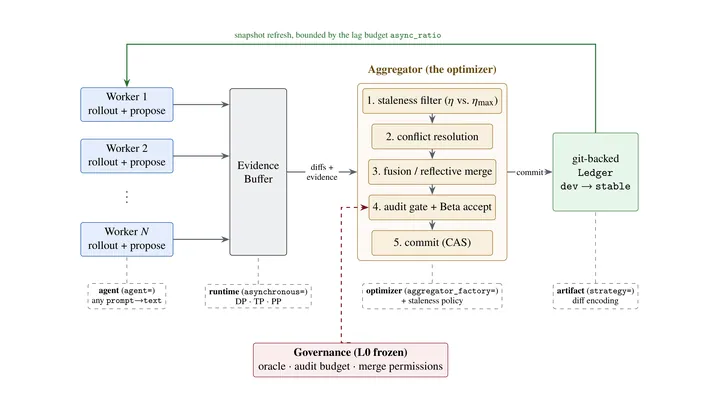
The loop: The agentdescent framework treats agent parameters like skills and harnesses as optimizable components. This allows an optimizer to compute diffs as gradients and update the agents, enabling them to evolve their own components to improve performance.

A parallel, asynchronous framework that applies gradient descent concepts to self-evolving agents.

loop fit 6/10Birfyvia GitHub
Birfy/agentdescent

← 7 Oct 2026 Latest