SEAL
Self-Adapting Language Models (SEAL)SEAL is a framework in which a language model writes self-edits, its own finetuning data and update directives, and applies them to its own weights through supervised finetuning.
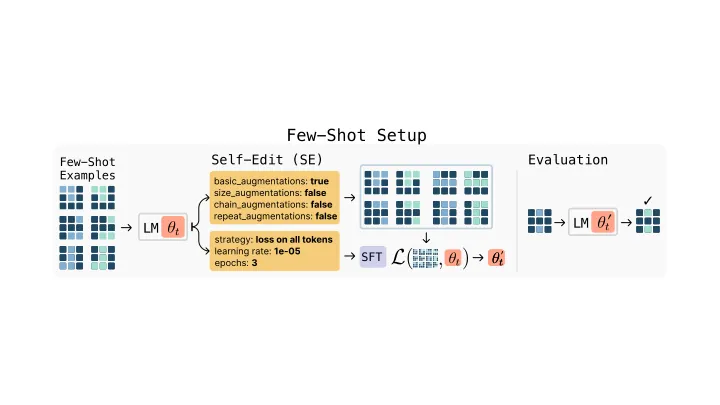
The language model generates a self-edit for a new input (restructured training data, optimization hyperparameters or augmentation calls), and the edit is applied as a persistent weight update through SFT. Reinforcement learning then rewards each self-edit by the downstream performance of the updated model, so the model learns to write better training data for itself.
- Language model generates a self-edit
- Edit is applied as weight update
- RL rewards self-edit by downstream performance
- Language model generates a self-edit
- Edit is applied as weight update
- RL rewards self-edit by downstream performance
Why it is a road to recursion
The model is both the author of its training data and the trainee, and the author is optimized by how much its own update helped, which is a direct self-modification loop over weights.
Evidence
In single-passage knowledge incorporation, two rounds of ReST-EM raised QA accuracy from 32.7% (no adaptation) to 47.0%, ahead of finetuning on raw passages or on synthetic data generated by GPT-4.1.
Related loops
More training data →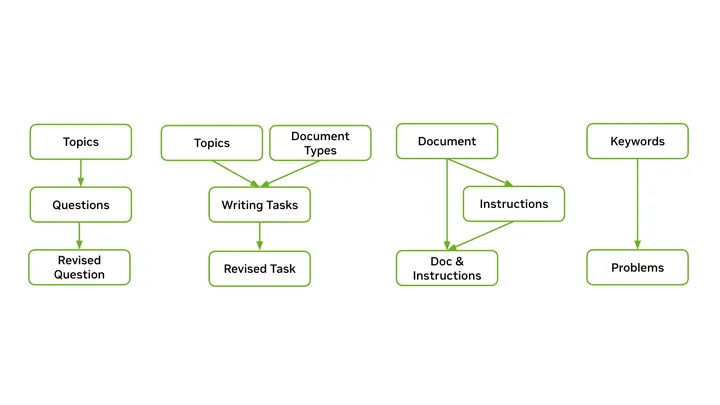
- Aligned model generates training data
- Reward model judges and filters it
- Data trains next intermediate instruct model
- Next model generates better alignment data
- repeat
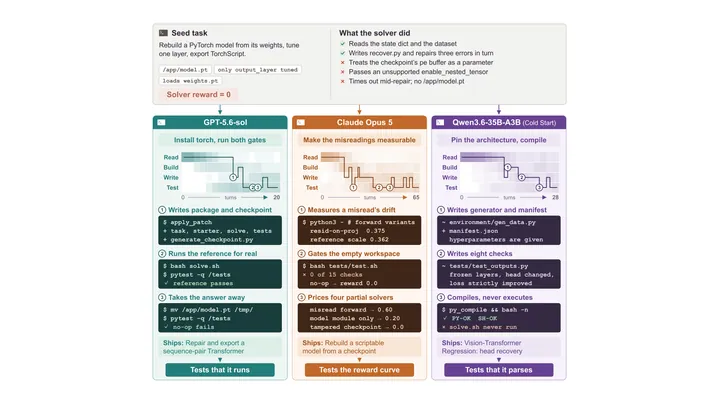
- Proposer agent builds environments
- Solver generates rollouts
- Rollouts guide next environments
- Solver trains on new environments
- repeat
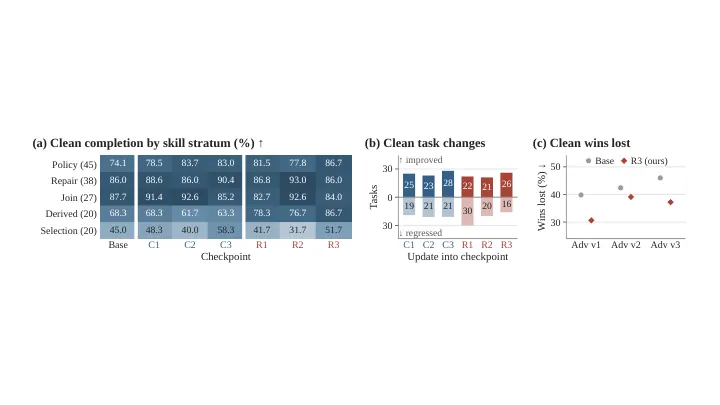
- Simulator co-evolves tasks and adversaries
- Generates challenging web agent scenarios
- Agent trains on resulting curriculum
- Agent handles harder tasks and attacks
- repeat