alphaBell Qwen Open
A 27B post-training research model from alphaBell. Study how weight editing and supervised fine-tuning change model behavior, with capability tradeoffs measured against the Qwen parent.
Explore the checkpoint
alphaBell-Qwen3.8-27B-Open combines abliteration with supervised fine-tuning to study refusal behavior. The FP8 checkpoint makes the model available in blockwise E4M3 format. The BF16 checkpoint is the reference for the coding results.
Download from GitHub
The client downloads the release parts, verifies their checksums and reconstructs the model files.
curl -fLO https://github.com/RotemAI/alphabell-qwen-open/releases/download/v0.1.0-fp8/download_model.py
python3 download_model.py --output ./alphaBell-Qwen3.8-27B-Open-FP8Coding capability tradeoffs
Full figure →The final BF16 checkpoint passes one more HumanEval task and fewer tasks on the other three suites. The comparison supports studying the tradeoff across tests.
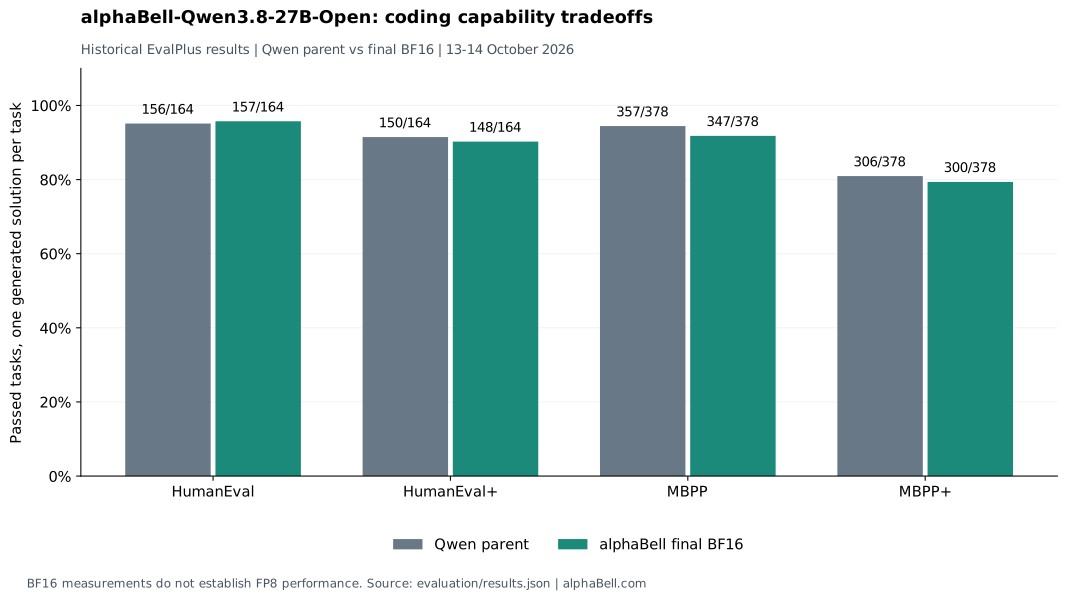
| Benchmark | Qwen parent | alphaBell BF16 | Change |
|---|---|---|---|
| HumanEval | 156/164 (95.12%) | 157/164 (95.73%) | +0.61 pp |
| HumanEval+ | 150/164 (91.46%) | 148/164 (90.24%) | -1.22 pp |
| MBPP | 357/378 (94.44%) | 347/378 (91.80%) | -2.65 pp |
| MBPP+ | 306/378 (80.95%) | 300/378 (79.37%) | -1.59 pp |
Temperature 0, maximum 16,384 generated tokens, thinking enabled, EvalPlus sanitization and scoring. The final HumanEval run had two token-limit truncations; MBPP had none. FP8 performance has not been benchmarked across these complete suites.
Lineage and research use
The parent is Qwen/Qwen3.8-27B, revision
1d4bf0f2ff6012fd82039f2fa52739d0dd7c60c0.
The model preserves the parent's vocabulary, added tokens and chat template.
Post-training includes 160 benign replay examples from Stanford Alpaca, sampled with seed 7. The derivative is licensed for noncommercial research. The original Qwen material retains its Apache 2.0 license; Alpaca data retains CC BY-NC 4.0 and its research-use notice.
Read the release license and upstream notices.
Use the right measurements
Refusal behavior, answer quality and successful task completion are distinct research questions. The reported coding comparison covers text generation. Vision, video and long-context quality have not been evaluated for this derivative.